Cloud OCR API alternative to Google Cloud Vision
Short answer
Cloud OCR free to start: FastOCR is a Google Vision API free alternative with a website, an API and offline apps, and no Google Cloud project to set up. Google Cloud Vision OCR pricing is per unit after a free monthly tier. For OCR without cloud API calls, use the free Mac and Windows apps or a self-hosted engine.
By the FastOCR team · Updated 4 November 2026 · Accuracy test run 31 October 2026
We make FastOCR. Accuracy figures come from our own test of each tool we scored, ours included, on the same scans; other facts link to each tool's own pages. How we tested
Try it here
Drop your file here
PDF, PNG, JPG, WebP, BMP, HEIC
PDF up to 1 GB · images up to 20 MB
Tips for a clear photo
- Lay the page flat.
- Use even light, with no shadows.
- Turn off the flash to avoid glare.
- Fill the frame with the page.
Verdict
Pick FastOCR if
- You want text or a searchable PDF from a photo or PDF without creating a Google Cloud project.
- You want a free website to try before you write code, with an API behind it.
- You send PDFs and would rather not stage them in a Cloud Storage bucket and read JSON back.
Pick Google Cloud Vision if
- You need word and symbol positions as JSON from the OCR response.
- You already run on Google Cloud and want billing and access control in one place.
- Your volume is high enough that the published per-unit price tiers decide.
FastOCR and Google Cloud Vision side by side
| Factor | FastOCR | Google Cloud Vision |
|---|---|---|
| What it is | FastOCRA website, a hosted REST API and free offline Mac and Windows apps (beta). | Google Cloud VisionA Google Cloud API, called with the credentials of a Google Cloud project.Source |
| Setup | FastOCRA free account and one API key for the API. Images on the website need no account. | Google Cloud VisionA Google Cloud project with a billing account linked and the Vision API enabled.Source |
| What comes back | FastOCRRaw text, and a searchable PDF for images and scanned PDFs. | Google Cloud VisionA structured, hierarchical response holding the extracted text.Source |
| Word positions | FastOCRNot returned. | Google Cloud VisionThe full-text response is organized into pages, blocks, paragraphs, words and symbols.Source |
| PDF input | FastOCRUpload a PDF to the website or the API. Scanned PDFs need a free account. | Google Cloud VisionPDF and TIFF only from Cloud Storage, with the JSON output written to a bucket; up to 2000 pages.Source |
| Free tier | FastOCRFree image OCR on the website with no watermark, and free API pages every month. | Google Cloud VisionThe first 1,000 units used each month are free; each PDF page is one unit.Source |
| Price after the free tier | FastOCRPaid plans and one-time packs are on the pricing page. | Google Cloud VisionDocument text detection is $1.50 per 1,000 units up to 5,000,000, then $0.60.Source |
| Languages | FastOCR100+ languages, detected automatically, including mixed pages. | Google Cloud VisionA list with Supported, Experimental and Mapped levels; the document text endpoint auto-detects the full set, and Urdu is Experimental.Source |
| Accuracy on the six scripts shown | FastOCRScored on six scripts shown against other tools; Google Cloud Vision was not part of that run. | Google Cloud VisionNot tested |
Why FastOCR
For developers
REST API, Python SDK, MCP server for AI agents, LangChain and LlamaIndex loaders.
See For developersFree use
Images: free, no sign-up, no watermark. PDFs: free account.
See Free useScanned PDFs
Scanned PDF in, searchable PDF out; text copies in the right order, including right-to-left.
See Scanned PDFsLanguages
100+ languages, detected automatically, including mixed pages.
Share of characters wrong on our evidence scans (lower is better): Arabic 2.6%, Urdu 9.1%, Bengali 7.4%, Tamil 2.2%, Chinese 1.0%.
See LanguagesOffline desktop apps
Free offline Mac and Windows apps (public beta): searchable PDF, text, Word and Markdown, nothing leaves your computer.
See Offline desktop apps
Proof
Google Cloud Vision has no score in our evidence, so this page does not rank it. The measured comparison below covers Tesseract, the self-hosted option, and FastOCR on the six scripts shown; lower is better.
Google Cloud Vision OCR pricing and the free tier
Google's pricing page, read on 4 November 2026, says the first 1,000 units used each month are free. Document text detection then costs $1.50 per 1,000 units up to 5,000,000 units and $0.60 per 1,000 above that. Charges are per image, and each page of a PDF counts as one image, so a 200-page PDF is 200 units. Google's setup guide lists a billing account among the first steps, so even the free tier sits behind a billing account.
The free routes here need no cloud project. Images on the website are free with no sign-up or watermark, and the API pricing page lists what comes after the free allowance. Every API account includes 20 free pages each month. Google lists cheaper tiers for very large volumes, so run your own numbers before you move a heavy workload.
What goes in and what comes out
FastOCR takes PDFs up to 1 GiB and PNG, JPG, JPEG, GIF, WebP and BMP images up to 20 MiB. You upload to a presigned URL, start the job, poll and download text or a searchable PDF. Google answers a small image request in one synchronous call, which is simpler for many tiny images.
PDFs work differently on Google's side. Its PDF guide says PDF and TIFF detection is only available for files in Cloud Storage buckets, writes its output as JSON to a bucket, and accepts files up to 2000 pages. That suits a pipeline already built on Google Cloud, and it is more setup than a website upload.
OCR without a cloud API
Google Cloud Vision is a hosted API, so every file crosses the network to a service. Two ways to avoid that: an offline desktop app, or an engine you install and run yourself.
FastOCR's free Mac and Windows apps are public betas. They read PDFs and images offline with the OCR built into the operating system and save a searchable PDF, text, Word and Markdown. They read the languages the operating system supports, which is fewer scripts than the website, and the accuracy figures on this page do not apply to them.
Tesseract is free, open source and offline, but it is a program you install, not a website, and it needs a language pack for each script. Its results are below.
Self-hosted OCR: what Tesseract scored
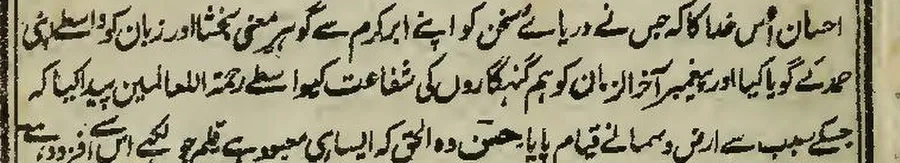
Tesseract 5.5.4 got 55.3% of the Urdu page's characters wrong against 9.1% for FastOCR, and 20.4% of the Arabic page against 2.6%; lower is better. The full numbers and caveats are on the FastOCR vs Tesseract page.
FastOCR
احسان اُس خدا کا کہ جس نے دریائے سخن کو اپنے ابر کرم سے گو ہر معنی بخشا اور زبان
کو واسطے اپنی
حمد کے گویا کیا اور پیغمبر آخرالزمان کو ہم گنہگاروں کی شفاعت کی اسے رحمتہ اللعالمین پیدا کیا کہ
Tesseract 5.5.4, Urdu pack
ا احمان اس دا اجس ےه در را سخ نکو ان ارک سےکوس ین یناد زا نک ری
ےکو پیا اد لزا نکوپرگن گا رو ںکی ضذاع تکھوا حطهنکتاللرا می نہیکںہ% of characters wrong by script, lower is better
- FastOCR
- Tesseract 5.5.4 (open source)
- OCR.space Engine 3
- imagetotext.info
| Script | Character error rate by tool |
|---|---|
| Chinese | FastOCR 1.0% Tesseract 71.9% OCR.space E3 no score |
| Tamil | FastOCR 2.2% Tesseract 8.5% OCR.space E3 no score |
| Arabic | FastOCR 2.6% Tesseract 20.4% OCR.space E3 2.9% imagetotext.info 2.9% |
| English | FastOCR 3.3% Tesseract 8.5% OCR.space E3 no score |
| Bengali | FastOCR 7.4% Tesseract 31.7% OCR.space E3 11.2% imagetotext.info 7.9% |
| Urdu | FastOCR 9.1% Tesseract 55.3% OCR.space E3 19.6% imagetotext.info 9.2% |
From a PDF to a searchable PDF with the API
Install the Python SDK from PyPI with pip install fastocr-sdk and set your API key in the environment. The quickstart shows the same job in cURL and Node.js, and the OCR API page covers limits and output. For AI agents in desktop assistants and code editors, the MCP server runs with uvx fastocr-mcp.
Nothing here needs a cloud project or a storage bucket: the SDK uploads the file, waits for the job and returns the searchable PDF or the text.
Choose Google Cloud Vision if
- You need coordinates for every word as JSON; the full-text response gives them and FastOCR does not.
- Your files, billing and access control already live in Google Cloud, and OCR should sit beside them.
- You send millions of units a month, where the published price tiers beat any feature list.
FAQ
What is a good alternative to the Google Cloud Vision API for PDF OCR?
FastOCR's document OCR API takes a PDF, runs the job and returns text or a searchable PDF, with no Google Cloud project or Cloud Storage bucket. Google Cloud Vision is the better fit when you need word boxes as JSON or already run on Google Cloud.
Is Google Cloud Vision OCR free?
Only a small part. Google's pricing page, read on 4 November 2026, says the first 1,000 units each month are free and each PDF page is one unit. Document text detection then costs $1.50 per 1,000 units up to 5,000,000 and $0.60 above that.
Can I use OCR without a cloud API?
Yes. Tesseract is free, open source and runs on your own machine, though you install it yourself and it has no web page. FastOCR's free Mac and Windows apps (public betas) read files offline with the operating system's OCR. The FastOCR website and API are hosted, so files are uploaded.
Is there a self-hosted alternative to a cloud OCR API?
Tesseract is the usual open-source choice. It got 55.3% of the Urdu page wrong in our run against 9.1% for FastOCR; lower is better, and tuning may help. You also take on the setup, the servers and the upkeep.
Does the FastOCR API return word bounding boxes?
No. It returns text or a searchable PDF whose invisible text layer sits on the scanned page. If your application needs word coordinates as JSON, use Google Cloud Vision, whose full-text response is organized down to words and symbols.
Did you compare FastOCR with Google Cloud Vision for accuracy?
No. Google Cloud Vision was not part of our test, so this page makes no accuracy claim about it. The accuracy figures here cover Tesseract and FastOCR on the six scripts shown, scored on 31 October 2026; lower is better.
Method
Google Cloud Vision facts come from its setup, full-text, PDF, language and pricing pages, re-read on 4 November 2026; prices are quoted from the pricing page that day. We did not run Google Cloud Vision. Accuracy figures come from our free-tool test of 31 October 2026, which scored one public-domain page per script by the share of characters wrong against the Wikisource text; lower is better. Tesseract 5.5.4 was run on a local machine at 1,280 px with default settings, and FastOCR's outputs date from 25 October 2026.
Change log
- 1 November 2026: First published with measured Tesseract results.
- 4 November 2026: Moved to the comparison template; pricing and PDF limits re-read from Google, languages and word positions added.