Tesseract OCR online? A Tesseract OCR alternative with no install
Short answer
Looking for a Tesseract bot alternative or the best Tesseract alternative? Tesseract is a program you install, not a website. FastOCR is the browser option: drop in an image or scanned PDF and get text, a searchable PDF, Word or Markdown with no setup. Keep Tesseract when OCR must run free on your own machine.
By the FastOCR team · Updated 4 November 2026 · Accuracy test run 31 October 2026
We make FastOCR. Accuracy figures come from our own test of each tool we scored, ours included, on the same scans; other facts link to each tool's own pages. How we tested
Try it here
Drop your file here
PDF, PNG, JPG, WebP, BMP, HEIC
PDF up to 1 GB · images up to 20 MB
Tips for a clear photo
- Lay the page flat.
- Use even light, with no shadows.
- Turn off the flash to avoid glare.
- Fill the frame with the page.
Verdict
Pick FastOCR if
- You searched for Tesseract OCR online and want a website: drop in a file, with nothing to install and no language files to download.
- You have a scanned PDF and want a searchable PDF back, not a folder of page images to feed to a command line.
- Your pages are in Urdu, Chinese or Bengali, where a local Tesseract run in our test got many times more characters wrong.
- You want OCR from code without running an engine yourself: FastOCR has a REST API and a Python SDK.
Pick Tesseract if
- You want a free, open-source library you can script, tune and run on your own machine.
- A document must never leave your computer, and you are happy to install and maintain the engine.
- You need hOCR, TSV, ALTO or PAGE output, which FastOCR does not offer.
FastOCR and Tesseract side by side
| Factor | FastOCR | Tesseract |
|---|---|---|
| How you use it | FastOCROpen the website in a browser or call the hosted API; free offline Mac and Windows apps are in beta. | TesseractA command-line program and a library. It has no built-in GUI.Source |
| Cost | FastOCRImages free with no sign-up or watermark; PDFs need a free account. Paid plans and one-time packs on the pricing page. | TesseractFree software under the Apache License 2.0.Source |
| Setup | FastOCRNone on the website. | TesseractInstall the engine, then a trained-data file for each language you need.Source |
| Scanned PDFs | FastOCRUpload the PDF and get a searchable PDF back; the text copies in reading order, right-to-left included. | TesseractWrites a searchable PDF from an image. Its README says input is opened as images, not documents like PDF.Source |
| Outputs | FastOCRRaw text, searchable PDF, Word (.docx) and Markdown. | TesseractPlain text, hOCR, PDF, TSV, ALTO and PAGE.Source |
| Recognition languages | FastOCR100+ languages, detected automatically. | TesseractMore than 100, chosen by you.Source |
| Picks the language for you | FastOCRYes, including mixed pages. | TesseractNo. You name the language with -l and can combine several, such as eng+deu.Source |
| Where your file goes | FastOCRUploaded to FastOCR on the website and API; the Mac and Windows apps work offline. | TesseractIt runs on your own machine.Source |
| Accuracy on our six test scans | FastOCRFewer characters wrong than a local Tesseract run on 6 of 6 scans, and inside the noise on . Lower is better. | Tesseract55.3% of the Urdu page wrong and 71.9% of Chinese; 8.5% on English and 8.5% on Tamil. Lower is better.Our test |
Why FastOCR
Photos and screenshots
Every image upload gets raw text and a single-page searchable PDF, plus Word and Markdown.
See Photos and screenshotsScanned PDFs
Scanned PDF in, searchable PDF out; text copies in the right order, including right-to-left.
See Scanned PDFsLanguages
100+ languages, detected automatically, including mixed pages.
Share of characters wrong on our evidence scans (lower is better): Arabic 2.6%, Urdu 9.1%, Bengali 7.4%, Tamil 2.2%, Chinese 1.0%.
See LanguagesFor developers
REST API, Python SDK, MCP server for AI agents, LangChain and LlamaIndex loaders.
See For developersOffline desktop apps
Free offline Mac and Windows apps (public beta): searchable PDF, text, Word and Markdown, nothing leaves your computer.
See Offline desktop apps
Proof
Tesseract is free software, so the run below is our own: version 5.5.4 with the matching language pack and no preprocessing, on the same 6 scans as FastOCR. FastOCR had the lower error rate on 6 of them, and was inside the noise (lower is better; gaps under 3 points count as ties). Tesseract's best pages were English and Tamil, at 8.5% and 8.5% wrong.
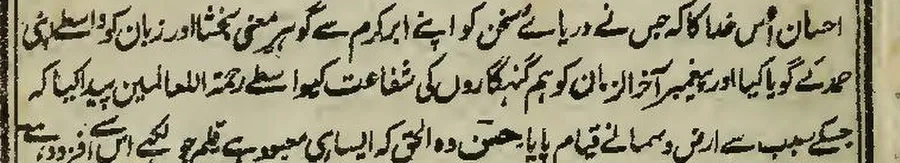
FastOCR
احسان اُس خدا کا کہ جس نے دریائے سخن کو اپنے ابر کرم سے گو ہر معنی بخشا اور زبان
کو واسطے اپنی
حمد کے گویا کیا اور پیغمبر آخرالزمان کو ہم گنہگاروں کی شفاعت کی اسے رحمتہ اللعالمین پیدا کیا کہ
Tesseract 5.5.4, Urdu pack
ا احمان اس دا اجس ےه در را سخ نکو ان ارک سےکوس ین یناد زا نک ری
ےکو پیا اد لزا نکوپرگن گا رو ںکی ضذاع تکھوا حطهنکتاللرا می نہیکںہ% of characters wrong by script, lower is better
- FastOCR
- Tesseract 5.5.4 (open source)
- OCR.space Engine 3
- imagetotext.info
| Script | Character error rate by tool |
|---|---|
| Chinese | FastOCR 1.0% Tesseract 71.9% OCR.space E3 no score |
| Tamil | FastOCR 2.2% Tesseract 8.5% OCR.space E3 no score |
| Arabic | FastOCR 2.6% Tesseract 20.4% OCR.space E3 2.9% imagetotext.info 2.9% |
| English | FastOCR 3.3% Tesseract 8.5% OCR.space E3 no score |
| Bengali | FastOCR 7.4% Tesseract 31.7% OCR.space E3 11.2% imagetotext.info 7.9% |
| Urdu | FastOCR 9.1% Tesseract 55.3% OCR.space E3 19.6% imagetotext.info 9.2% |
Is there a Tesseract OCR online?
Not from the Tesseract project. Its README describes a command-line program and a library, and its documentation says it has no built-in GUI. A page offering Tesseract OCR online is therefore somebody else's website.
Two sites say so themselves. NewOCR says its service is "based on the Tesseract OCR engine", and imagetotext.info says it is "powered with tesseract-ocr". We repeat those claims and nothing more. imagetotext.info scored close to FastOCR on our scans and far above our local Tesseract run, so we offer no explanation for its result.
FastOCR is a separate option in the same place: open the site, drop in an image or a scanned PDF, and read or download the result. Images need no account and carry no watermark; a scanned PDF needs a free account. For the hands-on side, what you would install and how, read Is Tesseract OCR free?.
Tesseract bot alternative: a website instead of something you host
A Tesseract bot is usually a chat bot that passes your photo to a Tesseract installation. One example is caiopo/tesseract-bot, a Telegram bot whose README says you must have Tesseract and its language packs installed. You host it, so you also keep it running.
If all you want is to send a picture and get text back, FastOCR is a website rather than a bot: nothing to host, and no token to create. From code, call the OCR API instead. A self-hosted bot remains the right call when the images must stay on a server you run.
What Tesseract needs before it reads a scan well
Tesseract's quality guide says it works best on images of at least 300 dpi and, for the 4.x series, on dark text against a light background. Dark pages, low-resolution photos and skewed scans need preparation before they reach the engine. Its FAQ adds that handwriting will not work very well, because it is designed for printed text.
Our test used none of that preparation. We ran version 5.5.4 with the matching language pack and no preprocessing, so the figures show an out-of-the-box result. A tuned pipeline, other models or cleaner input could lower its error rate, and we did not try any of them. If your scans are already clean and you can script the preparation, Tesseract may beat the numbers on this page.
Language is a second setup step. Its command-line guide shows naming the language with -l, and the data files page lists a separate file for each one. FastOCR detects the language of each page itself.
Tesseract alternatives, by what you need
- A website, one file, now: upload it to FastOCR and copy the text or download a searchable PDF.
- A scanned PDF that must be searchable: make the PDF searchable and the text layer copies in reading order.
- OCR inside your own code, without operating an engine: the OCR API and Python SDK, with the calls in the docs.
- Offline on one computer: the free Mac and Windows apps recognise text and export it, with nothing leaving your machine. They use the text recognition built into macOS and Windows, so the accuracy figures on this page do not apply to them. Both are unsigned public betas.
- A library you control end to end: stay with Tesseract.
Tesseract OCR for Uzbek
The data files page lists two Uzbek models: uzb for Latin script and uzb_cyrl for Cyrillic. You install the one that matches your document, and a page that mixes both scripts needs both.
FastOCR lists Uzbek and detects whether a page is Latin or Cyrillic, so there is nothing to choose. See the Uzbek OCR page. We did not test Uzbek, so we give no accuracy figure for either tool. Try one of your own pages in both before you decide.
Choose Tesseract if
- You are a developer who wants free, open-source OCR under your control, with your own choice of settings and preprocessing.
- The documents are private and must be recognised on a machine you run, with no upload.
- You need hOCR, TSV, ALTO or PAGE output, or a language model you pick and install yourself.
FAQ
Is there a Tesseract OCR online?
Tesseract is a program you install, so the project has no site to upload to. Some websites say they run it: NewOCR says it is based on the Tesseract OCR engine and imagetotext.info says it is powered with tesseract-ocr. FastOCR is a separate browser tool with no install.
What is a Tesseract bot, and what is an alternative?
Most Tesseract bots are self-hosted chat bots, such as the Telegram bot caiopo/tesseract-bot, that call a Tesseract installation you provide. FastOCR is not a bot. It is a website: drop in a file and read or download the result, or call the API from code.
Is FastOCR a good Tesseract OCR alternative?
If you want results without setup, yes. On our six-script test it had the lower error rate than a local Tesseract run on 6 scans and was inside the noise on . If you want a free library to script, tune and run offline, Tesseract fits better.
Could a tuned Tesseract score better than your test?
Yes. We ran Tesseract 5.5.4 with the matching language pack and no preprocessing. Its own guide recommends at least 300 dpi and dark text on a light background, so cleaning images first, or using other models, may lower its error rate. Our figures show an out-of-the-box result.
Does Tesseract make searchable PDFs?
Yes. Its command-line guide shows PDF output with an invisible text layer from an image. You install it, feed it page images and manage language data yourself. FastOCR takes a scanned PDF as the upload and returns a searchable PDF, with right-to-left text copying in order.
Does Tesseract support Uzbek?
Yes. Its data files list both uzb for Latin script and uzb_cyrl for Cyrillic, and you install the one that matches your script. We did not test Uzbek, so we have no accuracy figure for either tool. FastOCR lists Uzbek and detects Latin or Cyrillic on its own.
Is my file uploaded?
On the website and API, yes: FastOCR processes files in the cloud. Tesseract runs on your own machine, so choose it when a document must not leave your computer. The free Mac and Windows apps (public beta) also work offline.
Method
Every Tesseract fact on this page comes from the project README or one of its documentation pages (install, command line, data files, quality guide, FAQ), read again on 4 November 2026. What NewOCR and imagetotext.info say about themselves is quoted from their home pages. Accuracy comes from a test we ran on 31 October 2026: one public-domain scanned page per script, scored by the share of characters wrong against the Wikisource text, so lower is better. Tesseract 5.5.4 ran on our machine with the matching language pack and no preprocessing. FastOCR's output is from its production API on 25 October 2026. For Arabic, Urdu and English, FastOCR read 500-pixel-wide copies while Tesseract got 1,280 pixels. Gaps under 3 points count as ties. We did not test Uzbek, NewOCR or the bots.
Change log
- 27 June 2026: First published.
- 31 October 2026: Added the script-by-script test against a local Tesseract run.
- 4 November 2026: Moved to the comparison template; added the Tesseract setup, bot and alternatives sections, and re-read the Tesseract documentation.