Japanese OCR — Image to Text & PDF
無料オンラインOCR — 画像からテキストを抽出
画像やスキャン文書から日本語テキストを正確に抽出
- All Japanese scripts
- Vertical & horizontal
- Signs & menus
Free image OCR. No account needed. PDFs use pages.
Supreme Court rule, 2001
Real scan. Unedited OCR.
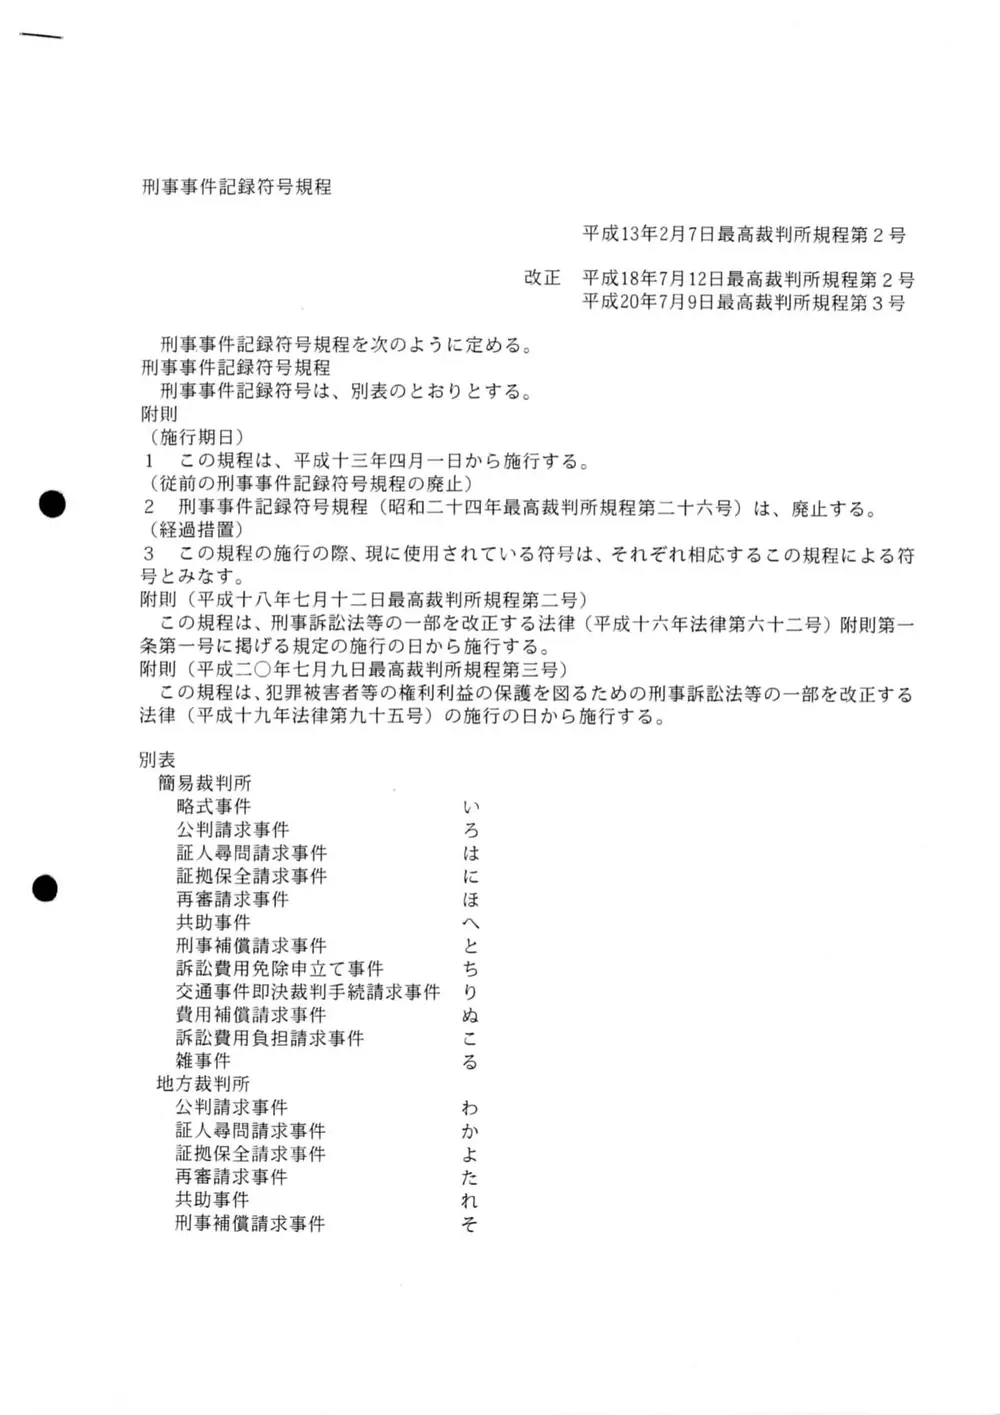
刑事事件記録符号規程
平成13年2月7日最高裁判所規程第2号
改正 平成18年7月12日最高裁判所規程第2号
平成20年7月9日最高裁判所規程第3号
刑事事件記録符号規程を次のように定める。
刑事事件記録符号規程
刑事事件記録符号は、 別表のとおりとする。
附則
(施行期日)
1 この規程は、 平成十三年四月一日から施行する。
(従前の刑事事件記録符号規程の廃止)
2 刑事事件記録符号規程(昭和二十四年最高裁判所規程第二十六号) は、 廃止する。
(経過措置)
3 この規程の施行の際、現に使用されている符号は、それぞれ相応するこの規程による符
号とみなす。
附則(平成十八年七月十二日最高裁判所規程第二号)
この規程は、 刑事訴訟法等の一部を改正する法律(平成十六年法律第六十二号) 附則第一
条第一号に掲げる規定の施行の日から施行する。
附則(平成二〇年七月九日最高裁判所規程第三号)
この規程は、犯罪被害者等の権利利益の保護を図るための刑事訴訟法等の一部を改正する
法律(平成十九年法律第九十五号) の施行の日から施行する。
別表
簡易裁判所
公判証人略式尋問事件 請求事件 請求事件 いろは
証保全請求事件 に
刑事訴訟交通再審共助費用事件 事件請求補償免除事件 請求即決事件 裁判申立手続て事件 請求事件 ほへとちり
費用訴訟雜事件 補償費用負担請求請求事件 事件 ぬこる
地方裁判所
公判証人尋問請求請求事件 事件 わか
再審共証請求事件 保全請求事件 事件 よたれ
刑事補償請求事件 そ
Original text order preserved
Japanese OCR converts images, scans and PDFs containing Japanese (日本語) text into editable, searchable digital text. FastOCR reads Japanese online: upload an image with no account, or a PDF with a free account, then copy the text or download a searchable PDF. Accuracy depends on scan quality, so check the result against your original.
Try it with your Japanese document
Drop your file here
PDF, PNG, JPG, WebP, BMP, HEIC
PDF up to 1 GB · images up to 20 MB
Tips for a clear photo
- Lay the page flat.
- Use even light, with no shadows.
- Turn off the flash to avoid glare.
- Fill the frame with the page.
What is Japanese OCR & Developer API?
Developer API docs →Japanese OCR is the automated process of converting scanned multi-page PDFs up to 1GB and documents into editable, searchable Japanese text while preserving accents, complex ligatures, and native character shapes. FastOCR reads printed text in this script and generates full-text searchable PDFs with selectable text overlays. For engineering teams building RAG pipelines, vector search databases, or automated document ingestion, FastOCR also provides a Japanese OCR REST API at api.fastocr.org with 50 free pages a month for every signed-in account. The API accepts PDF files up to 1 GiB, and PNG, JPG, JPEG, GIF, WebP and BMP images up to 20 MiB. An image counts as one page.
All Japanese scripts
Kanji, hiragana, katakana, and romaji recognized in the same document.
Vertical & horizontal
Both tategaki (vertical) and yokogaki (horizontal) text layouts.
Signs & menus
Photograph Japanese signs, restaurant menus, or product labels.
Documents & books
Scanned Japanese documents, textbooks, and manga pages.
Mixed languages
Japanese mixed with English or other languages in the same image.
Translate after extraction
Extract Japanese text then translate to English or any language.
日本語OCRが難しい理由
- Recognizing three distinct writing systems (hiragana, katakana, kanji) intermixed in a single sentence
- Handling vertical text layouts (tategaki) common in novels, newspapers, and traditional documents
- Distinguishing between thousands of visually similar kanji characters with subtle stroke differences
- Processing furigana (small reading aids above kanji) without merging them into the main text line
- Correctly segmenting Japanese text which has no spaces between words
PDFや画像から日本語テキストを抽出する方法
- Go to fastocr.org
- 日本語の画像またはPDFをアップロードしてください。言語は自動的に検出されます。
- 処理を待ちます — 画像は数秒、PDFは進行バーが表示されます。
- 結果をダウンロード:検索可能なPDF、テキストファイル、またはテキストを直接コピーします。
日本語OCRの精度を上げるためのヒント
- Specify vertical text mode if your document uses tategaki (top-to-bottom) layout
- Use 300+ DPI scans to preserve fine stroke details that distinguish similar kanji
- For documents with furigana, expect the small reading text to appear inline — manual cleanup may be needed
- Crop headers and footers before processing to avoid mixing navigation text with body content
- Review kanji carefully — visually similar characters like 土/士, 末/未, 大/犬 are common OCR errors
日本語OCRの一般的な使用例
- Digitizing Japanese business contracts and corporate filings
- Extracting text from Japanese manga and light novel scans for translation
- Converting scanned Japanese academic papers and patent documents
- Processing Japanese government forms, tax documents, and certificates
- Archiving historical Japanese texts printed in traditional vertical layout
FastOCR vs Standard OCR Apps for Japanese
| Capability | FastOCR Dedicated Cloud AI | Standard Online OCR Tools |
|---|---|---|
| Japanese Script Recognition | ✅ Full native cloud recognition for Japanese (complex alphabets and diacritics) | Limited character sets or unhandled accents |
| Multi-Column & Table Layouts | ✅ Preserves proper paragraph and table alignment | Merges unrelated columns together |
| Searchable PDF/A Output | ✅ Dual-layer searchable PDF with coordinate-aligned text overlay | Plain unformatted text dump only or unsupported |
| Instant Web Access | ✅ Zero software installation (runs in mobile & desktop browser) | Requires local CLI libraries or complex desktop setup |
よくある質問
Does Japanese OCR handle all three writing systems?
Yes. FastOCR recognizes hiragana, katakana, and kanji in the same document, including mixed text with English characters.
Can it read vertical Japanese text?
Yes. Our advanced AI engine supports vertical (tategaki) text recognition. For best results, ensure the scan is straight and not rotated.
How accurate is Japanese OCR on kanji?
FastOCR reads printed Japanese text. Complex or rare kanji may have lower accuracy — always review output.
Is Japanese OCR free?
Image OCR is free with no registration. PDF processing requires a free account — see fastocr.org/pricing for plan details.
How does FastOCR handle mixed kanji, hiragana, and katakana?
Japanese text switches between three scripts within the same sentence — kanji for content words, hiragana for grammar, and katakana for foreign loanwords. FastOCR's AI models are trained on all three simultaneously, recognizing script boundaries and extracting text with correct script allocation.
Can Japanese OCR process formal vs informal writing styles?
Yes. Formal Japanese uses kanji extensively with minimal kana, while informal writing (especially online) uses more hiragana and fewer kanji. FastOCR handles both styles. Formal documents like contracts and legal papers and informal text like social media screenshots can both be read, so always review the output.
Dedicated Japanese Tools
PDF to Text
Convert and extract Japanese documents.
Image to Text
Convert and extract Japanese documents.
Handwriting OCR
Convert and extract Japanese documents.
Searchable PDF
Convert and extract Japanese documents.
Japanese to English Translation
Convert and extract Japanese documents.
English to Japanese Translation
Convert and extract Japanese documents.
All supported languages
Convert and extract Japanese documents.
Explore Specialized OCR Workflows
FastOCR provides dedicated AI text recognition engines optimized for complex document types and formats:
Free for images. No registration required.
Related Articles & Resources
Japanese OCR Guide
In-depth guide to Japanese OCR with kanji, hiragana, and katakana
Chinese OCR
OCR for Chinese characters — shares kanji with Japanese
Korean OCR
Extract text from Korean Hangul documents
Image to Text
Convert any image to editable text instantly
PDF to Text
Extract text from scanned and native PDFs
FastOCR vs Google Cloud Vision
Compare FastOCR with Google Cloud Vision for Japanese OCR
What is OCR?
Learn how optical character recognition technology works.
Free Japanese OCR
Upload & Extract TextLast updated: July 24, 2026