Amazon Textract alternatives: a self-hosted alternative to AWS Textract, or a hosted API
Short answer
AWS Textract vs Google Vision comes down to setup and scope: both are cloud APIs that return structured JSON, and neither is scored here. Tesseract is the open-source route if OCR must run on your own machines. FastOCR is the hosted route: an API that returns text or a searchable PDF, with no AWS account, IAM role or bucket to configure.
By the FastOCR team · Updated 4 November 2026 · Accuracy test run 31 October 2026
We make FastOCR. Accuracy figures come from our own test of each tool we scored, ours included, on the same scans; other facts link to each tool's own pages. How we tested
Try it here
Drop your file here
PDF, PNG, JPG, WebP, BMP, HEIC
PDF up to 1 GB · images up to 20 MB
Tips for a clear photo
- Lay the page flat.
- Use even light, with no shadows.
- Turn off the flash to avoid glare.
- Fill the frame with the page.
Verdict
Pick FastOCR if
- You want text or a searchable PDF back, not Block objects you have to turn into text yourself.
- Your pages are in Urdu, Persian, Bengali or Tamil, none of which the AWS language list names.
- You want a hosted API with a Python SDK and an MCP server, and no AWS account to run it.
Pick Amazon Textract if
- You need form fields, table cells or query answers from the same service.
- You already run on AWS and want IAM, S3 and billing in one place.
- Your PDFs run to thousands of pages and you want asynchronous jobs; AWS documents up to 3,000 pages per PDF.
FastOCR and Amazon Textract side by side
| Factor | FastOCR | Amazon Textract |
|---|---|---|
| How you call it | FastOCRA hosted REST API, a Python SDK and an MCP server, plus free offline Mac and Windows apps (beta). | Amazon TextractAn AWS API with synchronous operations for single pages and asynchronous ones for larger documents.Source |
| Account and setup | FastOCRA free account and one API key. Images on the website need no account. | Amazon TextractAn AWS account is needed; the free tier lasts three months for new AWS customers.Source |
| What comes back | FastOCRRaw text, and a searchable PDF for scanned PDFs and images. | Amazon TextractA list of Block objects for pages, lines and words; analysis operations add forms and tables.Source |
| Forms and tables | FastOCRNot returned as data. The output is text in reading order. | Amazon TextractYes. Its overview lists text, forms and tables.Source |
| Languages | FastOCR100+ languages, detected automatically, including mixed pages. | Amazon TextractMore than 40 listed, Arabic, Hindi, Chinese, Japanese, Korean and Hebrew among them; Forms calls cover six; handwriting is English only.Source |
| PDF limits | FastOCRScanned PDFs need a free account; limits are on the API pricing page. | Amazon TextractAsynchronous PDF and TIFF files up to 500 MB and 3,000 pages; synchronous ones take 1 page.Source |
| Price to start | FastOCRFree image OCR on the website and free API pages every month; paid plans are on the pricing page. | Amazon Textract$0.0015 per page for Detect Document Text, first million pages, US West (Oregon).Source |
| Accuracy on the six scripts shown | FastOCRScored on six scripts shown against other tools; Textract was not part of that run. | Amazon TextractNot tested |
Why FastOCR
For developers
REST API, Python SDK, MCP server for AI agents, LangChain and LlamaIndex loaders.
See For developersScanned PDFs
Scanned PDF in, searchable PDF out; text copies in the right order, including right-to-left.
See Scanned PDFsLanguages
100+ languages, detected automatically, including mixed pages.
Share of characters wrong on our evidence scans (lower is better): Arabic 2.6%, Urdu 9.1%, Bengali 7.4%, Tamil 2.2%, Chinese 1.0%.
See LanguagesExports
Raw text, Word (.docx) and Markdown.
See Exports
Proof
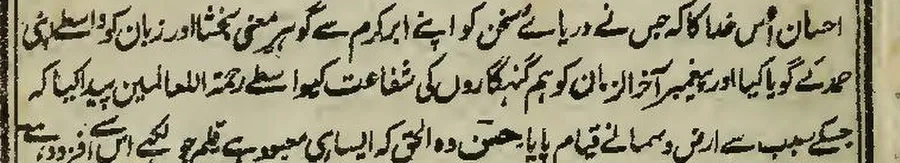
Amazon Textract has no score in our evidence, so nothing here ranks it. The chart shows FastOCR and Tesseract, the self-hosted option, on the six scripts shown; lower is better, and gaps under 3 points count as ties.
FastOCR
احسان اُس خدا کا کہ جس نے دریائے سخن کو اپنے ابر کرم سے گو ہر معنی بخشا اور زبان
کو واسطے اپنی
حمد کے گویا کیا اور پیغمبر آخرالزمان کو ہم گنہگاروں کی شفاعت کی اسے رحمتہ اللعالمین پیدا کیا کہ
Tesseract 5.5.4, Urdu pack
ا احمان اس دا اجس ےه در را سخ نکو ان ارک سےکوس ین یناد زا نک ری
ےکو پیا اد لزا نکوپرگن گا رو ںکی ضذاع تکھوا حطهنکتاللرا می نہیکںہ% of characters wrong by script, lower is better
- FastOCR
- Tesseract 5.5.4 (open source)
- OCR.space Engine 3
- imagetotext.info
| Script | Character error rate by tool |
|---|---|
| Chinese | FastOCR 1.0% Tesseract 71.9% OCR.space E3 no score |
| Tamil | FastOCR 2.2% Tesseract 8.5% OCR.space E3 no score |
| Arabic | FastOCR 2.6% Tesseract 20.4% OCR.space E3 2.9% imagetotext.info 2.9% |
| English | FastOCR 3.3% Tesseract 8.5% OCR.space E3 no score |
| Bengali | FastOCR 7.4% Tesseract 31.7% OCR.space E3 11.2% imagetotext.info 7.9% |
| Urdu | FastOCR 9.1% Tesseract 55.3% OCR.space E3 19.6% imagetotext.info 9.2% |
Self-hosted alternative to AWS Textract: Tesseract, measured
Tesseract is the usual answer when OCR has to run on hardware you control. It is Apache 2.0 software from the project repository, and its documentation says the install has two parts, the engine and the trained data for each language. It has no built-in window. It writes plain text, a searchable PDF, hOCR, TSV, ALTO or PAGE, and it does not return form fields or table cells, so that work stays with you.
Tesseract 5.5.4, installed locally with the matching language pack, got 55.3% of the Urdu page's characters wrong against 9.1% for FastOCR, and 20.4% of the Arabic page against 2.6%; lower is better. Tesseract's image-quality guide lists steps such as 300 dpi input and dark text on a light background, so a tuned setup may score better than this run. The Tesseract comparison has the full run.
AWS Textract vs Google Vision: what the documentation says
Both are cloud APIs that answer with structured data rather than a finished file, so the differences sit in setup and scope. Google's setup guide asks for a Google Cloud project with billing and the Vision API enabled, and its PDF page says PDF and TIFF detection works on files in Cloud Storage and writes JSON to a bucket, for up to 2000 pages. AWS runs single pages through synchronous operations and larger documents through asynchronous ones, as its workflow page describes.
On languages, Google's language page says the document text endpoint auto-detects its full set and labels each language Supported or Experimental, with Urdu Experimental. AWS names more than 40 languages and then narrows them by operation. Textract's overview lists forms and tables as outputs, which a text-only comparison would miss. Neither service was run on our scans, so this page ranks neither. The Google Cloud Vision comparison covers its pricing and free tier.
Forms, tables and queries: where Textract is the better fit
Textract exists for structured extraction. Its overview lists text, forms and tables, and its analysis operations return key-value pairs and table cells as Block objects your code can read. FastOCR returns text in reading order and a searchable PDF; it does not return form fields or table cells as data. If your application needs those, stay on Textract.
Price is the other reason to stay. AWS publishes a separate per-page rate for each operation on its pricing page, checked 4 November 2026, so the operation you call sets the bill. At high volume on AWS, that rate table decides more than any feature list.
Languages: what AWS lists now, and where the limits apply
AWS's quotas page says Textract supports more than 40 languages, among them Arabic, Hindi, Chinese, Japanese, Korean and Hebrew. The same page limits Forms calls to English, Spanish, Italian, Portuguese, French and German, says other APIs are limited to English, and limits handwriting to English. Read the page for the exact operation you plan to call before you commit to a script.
Urdu, Persian, Bengali, Tamil and Thai are not among the languages that page names. FastOCR detects the language of each page itself, including pages that mix scripts, so there is no per-request setting. On our test scans it got 9.1% of Urdu characters wrong, 7.4% of Bengali and 2.2% of Tamil; lower is better. Those are single public-domain pages per script, not a guarantee for your documents.
On-premise alternative to AWS Textract
FastOCR's website and API are hosted, so files are uploaded to FastOCR for processing; they are not an on-premise option. The free Mac and Windows apps read files offline on one computer and save a searchable PDF, text, Word and Markdown. They are public betas that recognise text and write files; they do not return forms or tables, and the accuracy figures on this page do not apply to them.
For a server deployment inside your own network, the open-source engine above is the route. You take on installing it, preparing the images and maintaining the servers, and you build any form or table extraction yourself.
A hosted API that returns a finished result
The OCR API takes an image or a PDF and returns text, or a searchable PDF for scanned pages, so there is no Block list to walk. Create one API key and follow the quickstart. The Python SDK is fastocr-sdk on PyPI, the MCP server fastocr-mcp lets AI agents read documents through the same API, and LangChain and LlamaIndex loaders are published.
Every API account includes 20 free pages each month, and paid options are on the API pricing page. The trade-off is where the file goes: each document you send is uploaded to FastOCR for processing, which matters for regulated work.
Choose Amazon Textract if
- Forms, key-value pairs or table cells are the data your application consumes; Textract's analysis operations return them.
- Your stack already lives on AWS, and IAM roles, S3 and one invoice matter more than the choice of OCR.
- You process large PDFs in bulk and want AWS asynchronous jobs, which its quotas page documents for up to 3,000 pages.
FAQ
What is a self-hosted alternative to AWS Textract?
Tesseract is free, open source and runs on your own machine. In our test it got 55.3% of the Urdu page wrong against 9.1% for FastOCR; lower is better, and tuning may improve it. It returns text, not Textract-style forms or tables.
AWS Textract vs Google Vision: which is better?
We have not tested either, so this page ranks neither. The vendors differ in documentation: AWS names more than 40 languages and narrows them by operation, while Google auto-detects its full set and marks Urdu Experimental. Textract adds forms and tables.
What is an alternative to Amazon Textract that returns a searchable PDF?
FastOCR's API returns a searchable PDF or text from a scanned PDF or image, with no AWS account, IAM role or bucket. Textract returns Block objects, so a text layer is code you write. It does not extract forms or tables.
Does Amazon Textract support Arabic or Hindi?
Yes. AWS's quotas page lists more than 40 languages, including Arabic, Hindi, Chinese, Japanese, Korean and Hebrew, then limits Forms calls to six languages and handwriting to English. It does not name Urdu, Persian, Bengali, Tamil or Thai.
Is there an on-premise alternative to AWS Textract?
Not from FastOCR's website or API, which are hosted. Its free offline Mac and Windows apps keep files on one computer but only recognise text. For a server inside your own network, self-hosted Tesseract is the open-source choice, and you maintain it.
Can FastOCR extract forms and tables like Textract?
No. FastOCR reads the text and keeps reading order, including multiple columns, but it does not return form fields or table cells as data. For key-value pairs and table cells in your own code, use Textract.
Method
Textract facts come from AWS documentation (quotas, workflows, response objects, pricing), re-read on 4 November 2026. Google Cloud Vision and Tesseract facts come from their own documentation, read the same day. We did not run Textract or Google Cloud Vision. Tesseract and FastOCR results come from our 31 October 2026 test of one public-domain page per script, scored by the share of characters wrong against the Wikisource text, so lower is better. Tesseract 5.5.4 used the matching language pack and default settings at 1,280 px; FastOCR's outputs date from 25 October 2026.
Change log
- 1 November 2026: First published with measured Tesseract results.
- 4 November 2026: Moved to the comparison template; AWS language list corrected, Google Vision and on-premise answers added.