Best Free OCR Tools in 2026: 10 Compared on Limits, Sign-up and an 8-Language Accuracy Test
Updated 31 October 2026 · 10 min read
The best free OCR software depends on your file. For photos and screenshots with no account, our pick for the best OCR online is FastOCR (we publish it): 100+ languages, no watermark. For the best free PDF OCR without registration, use PDF24. Google Drive suits small files, and OCR.space is the free OCR API.
We also ran the same 8 scanned pages through the tools. On Urdu, Persian and Chinese pages, Tesseract, the engine NewOCR says it uses, misread 55% to 80% of the characters. FastOCR misread 1% to 10.5%. Two free tools did about as well as FastOCR, and one beat it on Hindi. See the test.
Most free OCR tools work on a clean English page. They differ in what they cap, what they ask for and which scripts they list. Below: a quick-picks table, then each tool with its free limits as published on its own site in October 2026.
Quick picks
| If you need | Use | Why |
|---|---|---|
| A photo or screenshot, any language, no account | FastOCR | No sign-up for images, no watermark. Try 3 images a day without an account. Sign in for unlimited free image OCR. |
| A scanned PDF in Arabic, Urdu, Hebrew or another non-Latin script | FastOCR | In our font round-trip test, text in all 16 scripts we tried copied back out of the searchable PDF. PDFs need a free account. |
| Text only, and you already live in Google | Google Drive | Open the file with Google Docs. Files must be 2 MB or smaller. |
| A plain PDF, no registration | PDF24 | Free and ad-funded, no registration. Files are deleted after an hour. |
| Lots of images, no registration | NewOCR | Free with no stated cap on the number of files. |
| One page, deleted fast | i2OCR | One image or PDF page per run. Files are deleted after 30 minutes. |
| A free OCR API | OCR.space or the FastOCR API | OCR.space: 25,000 requests a month, 1 MB files. FastOCR API: 50 pages a month, shared with web PDFs. |
We publish FastOCR, so it is listed first and you should weigh that. The case for it rests on the facts in its entry below, and every other entry links to the tool's own page.
Have a photo or scan open right now?
Images work with no account, no install and no watermark. PDFs need a free account, which includes 50 document pages a month.
Quick comparison: what each free OCR tool gives back
Daily caps matter less than what you can do with the result. This table compares outcomes: whether you need an account, whether you get a searchable PDF with no watermark, whether you get a Word file, how the tool did on our Urdu, Persian and Bengali test pages, and how many files it takes at once.
| Tool | Sign-up needed | Searchable PDF, no watermark | Word file | Urdu / Persian / Bengali errors | Batch |
|---|---|---|---|---|---|
| FastOCR | Images: no. PDFs: free account | Yes | Yes, with ruled tables | 9.1% / 10.5% / 7.4% | Small batches on a free account, larger on paid plans |
| Google Drive | Google account | No, a Google Doc | Google Doc | Not tested | Not stated |
| PDF24 | No | Yes | Not stated | Not tested | No stated limit |
| iLovePDF | Not stated | Yes, 15 MB | Not on the free plan | Not tested | One task per batch |
| Adobe Acrobat online | To download | Yes, after sign-in | Not stated | Not tested | Not stated |
| OCR.space | Free API key | Watermarked | No | Engine 2: 30.4% / rejected / 100%. Engine 3: 19.6% / 7.8% / 11.2% | API, 1 MB files |
| i2OCR | Not stated | Yes | Yes | Not tested (CAPTCHA) | One page per run |
| NewOCR | No | Yes | DOC | 55.3% / 80.0% / 31.7% * | No stated file cap |
| OnlineOCR.net | Guests: 5 files an hour | No | Yes | Urdu 99.6%, no Persian or Bengali option | Guests: 5 files an hour |
| Convertio | After 10 pages | Yes | Yes | Not tested | Not stated |
Error rates are character error rates from our 31 October 2026 test; lower is better. * NewOCR sits behind a CAPTCHA, so the figure is Tesseract 5.5.4, the engine NewOCR says it uses, run with the right language pack. "Not stated" means the tool's own page does not say. Every other cell comes from the tool's entry below, which links its source.
Free OCR accuracy test: the same 8 pages in 8 languages
Limits tables do not tell you whether the text comes out right. On 31 October 2026 we ran eight public-domain scanned book pages, one each in Arabic, Urdu, Persian, Hindi, Bengali, Tamil, Chinese and English, through the free tools this page compares; FastOCR's output on the same pages came from its production API on 25 October. We scored each output against the page's Wikisource transcription by character error rate: the share of characters the tool got wrong, so lower is better.
On a clean English page every engine did fine. The gap opens on other scripts. Tesseract, the open-source engine NewOCR says it runs, misread 55.3% of the Urdu page, 80.0% of the Persian page and 71.9% of the Chinese page even with the right language pack. FastOCR's error rates on the same pages were 9.1%, 10.5% and 1.0%. OCR.space's default engine refused Arabic, Hindi and Persian outright. Here is the Urdu page, line one, as each tool returned it:
The scan: a page of the Urdu book Tota Kahani (written 1801)
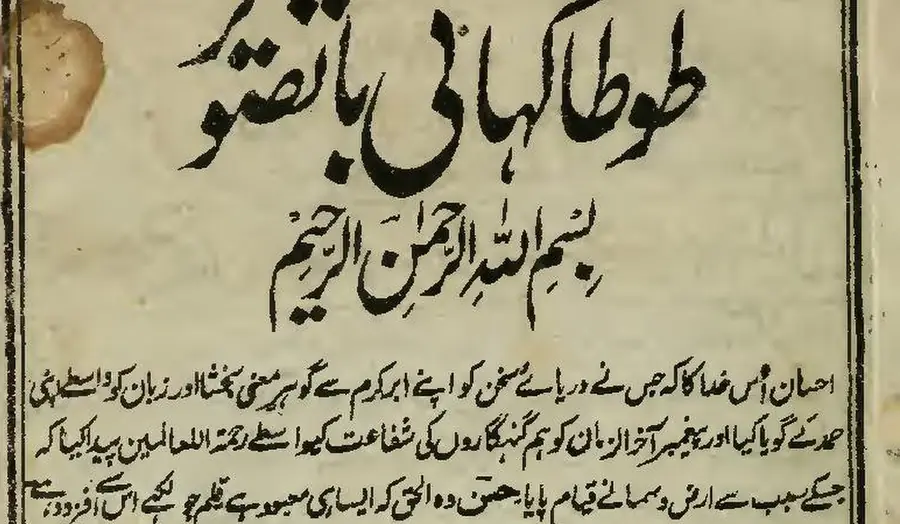
First body line, as printed (Wikisource transcription)
احسان اُس خدا کا کہ جس نے دریائے سخن کو اپنے ابر کرم سے گو ہرِ معنی بخشا اور زبان کو واسطے اپنی
- 9.1% of characters wrong
FastOCR
published by us
احسان اُس خدا کا کہ جس نے دریائے سخن کو اپنے ابر کرم سے گو ہر معنی بخشا اور زبان کو واسطے اپنی
- 9.2% of characters wrong
imagetotext.info
free web tool
احسان اُس خدا کا کہ جس نے دریائے سخن کو اپنے ابر کرم سے گو ہر معنی بخشا اور زبان کو واسطے اپنی
- 30.4% of characters wrong
OCR.space
default Engine 2
احسان أس مداكاكيج سنءريات سخن كواب ابركرم ← كوبر معى تختا اورزيان كوداسطيى
- 55.3% of characters wrong
Tesseract 5.5.4
the engine NewOCR says it uses
ا احمان اس دا اجس ےه در را سخ نکو ان ارک سےکوس ین یناد زا نک ری
- 99.6% of characters wrong
OnlineOCR.net
no Urdu option
tA)K11 tAirk.,....11.30,t4 ikitt r CIO 4 %;114iiii
Character error rate by script, lower is better
- FastOCR
- Tesseract 5.5.4 (the engine NewOCR says it uses)
- OCR.space default Engine 2
- Persian
- FastOCR:10.5%Tesseract 5.5.4 (the engine NewOCR says it uses):80.0%OCR.space default Engine 2:language rejected
- Chinese
- FastOCR:1.0%Tesseract 5.5.4 (the engine NewOCR says it uses):71.9%OCR.space default Engine 2:3.0%
- Urdu
- FastOCR:9.1%Tesseract 5.5.4 (the engine NewOCR says it uses):55.3%OCR.space default Engine 2:30.4%
- Bengali
- FastOCR:7.4%Tesseract 5.5.4 (the engine NewOCR says it uses):31.7%OCR.space default Engine 2:100.0%
- Arabic
- FastOCR:2.6%Tesseract 5.5.4 (the engine NewOCR says it uses):20.4%OCR.space default Engine 2:language rejected
- Hindi
- FastOCR:13.2%Tesseract 5.5.4 (the engine NewOCR says it uses):15.9%OCR.space default Engine 2:language rejected
- Tamil
- FastOCR:2.2%Tesseract 5.5.4 (the engine NewOCR says it uses):8.5%OCR.space default Engine 2:99.8%
- English
- FastOCR:3.3%Tesseract 5.5.4 (the engine NewOCR says it uses):8.5%OCR.space default Engine 2:4.5%
To be fair to the rest of the field: some free tools, such as imagetotext.info, read these scripts about as well as FastOCR, and on the Hindi page OCR.space's Engine 3 was clearly better. If one of them already fits your workflow, the accuracy is not a reason to switch.
| Tool | Arabic | Urdu | Hindi | Bengali | Persian |
|---|---|---|---|---|---|
| FastOCR | 2.6% | 9.1% | 13.2% | 7.4% | 10.5% |
| imagetotext.info | 2.9% | 9.2% | 14.5% | 7.9% | Not run |
| OCR.space Engine 3 | 2.9% | 19.6% | 2.7% | 11.2% | 7.8% |
Where FastOCR differs is what you get after the text is read: a searchable PDF whose hidden text copies out in the right order, a Word file with tables, and bank statements as spreadsheets. Method and caveats are in how we tested.
1. FastOCR
- Images need no account and carry no watermark. Try 3 images a day without an account. Sign in for unlimited free image OCR. Nothing to install.
- Reads 100+ languages and detects the language itself.
- In our font round-trip test, text in all 16 scripts we tried copied back out of the searchable PDF. Arabic, Urdu and Hebrew paste in the right order in Preview, poppler and MuPDF; Chrome's PDF viewer can scramble Latin text inside right-to-left lines.
- Reading order is column-aware, so a two-column page copies column by column instead of line across both.
- In our 8-page test it misread 9.1% of an Urdu page, 10.5% of a Persian page and 1.0% of a Chinese page, where Tesseract misread 55.3%, 80.0% and 71.9%. Its Hindi (13.2%) trailed OCR.space Engine 3 (2.7%).
- Downloads go beyond plain text: a Word file where prose reflows into paragraphs and ruled tables come back as Word tables, Markdown, and a searchable PDF with no watermark.
- Bank statements become Excel, CSV and QuickBooks files with the bank statement converter.
- A finished image can be translated or cleaned up with AI Polish. There are free offline apps for Mac and Windows, and an OCR API.
- PDFs need a free account. It includes 50 document pages a month; pricing covers packs and plans.
Best for: photos and scans in any language, and PDFs in right-to-left or CJK scripts where copy and search have to work afterwards.
Watch out for: the guest cap of 3 images a day, and PDFs need an account. Handwriting and poor scans need a proofread, as with every OCR tool.
Searchable PDF that copies in reading order
احسان اُس خدا کا کہ جس نے دریائے سخن کو اپنے ابر کرم سے گو ہر معنی بخشا اور زبان کو واسطے اپنی
Select and paste: Urdu, Arabic and Hebrew come out right to left, and two-column pages come out column by column.
Word file with paragraphs and tables
| Item | Qty | Total |
| Paper | 4 | 18.00 |
| Toner | 1 | 64.50 |
Prose reflows into editable paragraphs; ruled tables come back as real Word tables. PDF to Word
Bank statement to Excel, CSV or QuickBooks
| Date | Description | Amount | Balance |
| 09/01 | Rent payment | -1,450.00 | 968.65 |
| 09/02 | Payroll deposit | 2,386.40 | 3,355.05 |
| 09/04 | Grocery store | -84.17 | 3,270.88 |
One row per transaction, for US and UK statements in English (example rows invented). Bank statement converter
2. Google Drive (Google Docs)
- Free; you need a Google account.
- Files must be 2 MB or smaller. Accepts PDFs (including multipage) and JPEG, PNG or GIF photos.
- Language is detected automatically. Google lists Arabic, Urdu, Hebrew and Hindi among the supported languages.
- Bold, italics and line breaks usually carry over. Lists, tables, columns and footnotes often do not.
Best for: Plain text from a small file when you are already in Google Docs.
Watch out for: You get a Google Doc, not a searchable PDF. The 2 MB cap rules out most scans of a whole book.
Source: Google Drive Help, checked October 2026.
Compare in detail: FastOCR vs Google Drive OCR
3. PDF24 OCR
- Free and funded by ads. Its page says no registration is required and files are deleted from the server after one hour.
- The page advertises no limits and does not state a maximum file size.
- Arabic, Hebrew and Urdu are in its language list.
Best for: A scanned PDF you want searchable without making an account.
Watch out for: It does not publish a file size limit, so a large scan may still fail. Check a result before you rely on it.
Source: PDF24 OCR, checked October 2026.
Compare in detail: FastOCR vs PDF24
4. iLovePDF OCR PDF
- OCR PDF is available on the free Basic plan: one task per batch, up to 15 MB per task.
- The OCR versions of PDF to Word, PowerPoint and Excel are not included in Basic.
- Its language list includes Arabic, Hebrew, Hindi, Persian and Urdu.
Best for: People already using iLovePDF for merging, splitting and compressing.
Watch out for: One file at a time and a 15 MB ceiling on the free plan.
Source: iLovePDF pricing, checked October 2026.
Compare in detail: FastOCR vs iLovePDF
5. Adobe Acrobat online OCR
- Free to run. You can upload without signing in, but you have to sign in to download the searchable PDF.
- The page names English, German, Spanish, French and Portuguese, plus more on a linked list.
- OCR on PNG, JPG and TIFF files is part of the Acrobat Pro trial, not the free tool.
Best for: Clean Latin-script PDFs when you already have an Adobe account.
Watch out for: Check the language list for your script before uploading anything.
Source: Adobe online OCR, checked October 2026.
Compare in detail: FastOCR vs Adobe Acrobat
6. OCR.space
- Free API plan: 25,000 requests a month, files up to 1 MB, 3 PDF pages per document, and a rate limit of 500 requests a day per IP address.
- Engine 2 is the default and covers 33 languages. Engine 3 has its own quota of 1,000 conversions a month and auto-detects more than 200 languages.
- Searchable PDFs on the free plan carry a "Generated by OCR.space" watermark.
Best for: Developers who want a free API to prototype with.
In our test: In our 31 October 2026 test the default Engine 2 rejected Arabic, Hindi and Persian, and returned nothing usable for Bengali (100% character error rate) or Tamil (99.8%). Engine 3 did well: Arabic 2.9%, Hindi 2.7%, Persian 7.8%.
Watch out for: The watermark and the 1 MB cap make the free plan a testing tier.
Source: OCR.space API docs, checked October 2026.
Compare in detail: FastOCR vs OCR.space
7. i2OCR
- Free for one image or PDF page per run. Bulk OCR is a paid option.
- It claims 128 languages and scripts, and Arabic, Urdu and Hebrew are in the selector.
- Uploads and extracted text are deleted automatically after 30 minutes.
- Outputs include plain text, Word, HTML and searchable PDF.
Best for: One-off single pages where you want the file gone quickly.
In our test: We could not test i2OCR because the site sits behind a CAPTCHA.
Watch out for: One page per run gets slow past a handful of pages.
Source: i2OCR, checked October 2026.
8. NewOCR
- Free, no registration, and its page states no limit on the number of files.
- It lists 122 recognition languages, including Arabic, Hebrew and Urdu, and says it is based on the Tesseract engine.
- Takes common image formats, multipage TIFF, PDF and DjVu. Outputs TXT, DOC or PDF.
Best for: Plenty of images with no account.
In our test: NewOCR sits behind a CAPTCHA, so we ran Tesseract 5.5.4, the engine it says it is based on, with the right language pack. It misread more than half the characters on the Urdu, Persian and Chinese pages. English and Tamil pages came out far better (8.5% each).
Watch out for: It does not publish a file size or page limit. Look at the result before trusting it.
Source: NewOCR, checked October 2026.
Compare in detail: FastOCR vs Tesseract, the engine NewOCR names
9. OnlineOCR.net
- Guests get files up to 15 MB and 5 files an hour. Registered users get up to 200 MB and 50 free pages on signup.
- It lists 46 recognition languages. Arabic, Hebrew and Urdu are not on that list.
- Output is plain text, Word or Excel.
Best for: Latin-script documents when you want Word or Excel output.
In our test: With no Urdu option, our Urdu test page came back as Latin noise beginning "tA)K11 tAirk" (99.6% character error rate).
Watch out for: The page mentions Arabic, Hebrew and Urdu in its metadata but not in the language list. Test before you commit.
Source: OnlineOCR.net, checked October 2026.
Compare in detail: FastOCR vs OnlineOCR.net
10. Convertio OCR
- The OCR page shows 10 available pages before it asks you to sign up for more.
- You pick a main language and extra languages. Outputs include Word, Excel, searchable PDF and TXT.
Best for: A first try on one short document.
Watch out for: Ten pages is a trial allowance, not an ongoing free tier.
Source: Convertio OCR, checked October 2026.
Left out: Smallpdf, because we could not confirm its current free OCR limits from its own pages.
What your phone or computer already does
Apple's built-in OCR does not support Farsi, Urdu, Hindi, Hebrew or Bengali. Windows built-in OCR cannot read 25 of the 60 languages listed in FastOCR's Windows app, including Hindi, Urdu, Farsi and Thai. For English, French or Spanish a built-in tool is often enough. Outside those, you need a web tool. Details: OCR for non-Latin scripts and FastOCR vs Apple Live Text.
Free OCR APIs
Most hosted OCR APIs need an account and a key. OCR.space gives 25,000 requests a month but caps files at 1 MB and PDFs at 3 pages. The FastOCR API uses the same free monthly page allowance as PDFs on the website and returns text or a searchable PDF. Limits and sources for the other providers are in the free OCR API guide and the API comparison.
How to choose
- Check your script on the tool's language list first. If it is not listed, do not upload.
- Check the file cap. 2 MB (Google Drive), 15 MB (iLovePDF) and 1 MB (OCR.space API) rule out many scans.
- Decide what you need back. Plain text, Word, or a searchable PDF you can search and copy from.
- Test one real page. Paste the output into a text editor. For right-to-left text, check the first word sits at the right and numbers are intact.
How we tested
- Dates: the other tools ran on 31 October 2026; FastOCR's output came from its production API on 25 October 2026. Tools change, so we will re-run the test before quoting these numbers after January 2027.
- Pages: eight scanned book pages from Wikimedia Commons, all public domain or CC0, one per script. The reference text is each page's Wikisource transcription.
- Score: character error rate after removing spaces, punctuation and Arabic diacritics. The Wikisource text itself differs from our own proofread key by 1% to 6%, so gaps under about 3 points are noise.
- FastOCR got a smaller 500-pixel-wide image for the Arabic, Urdu and English pages; the other tools got 1,280 pixels.
- NewOCR sits behind a CAPTCHA, so we ran Tesseract 5.5.4, the engine NewOCR says it is based on, locally with the correct language pack. NewOCR's own settings may differ. i2OCR also sits behind a CAPTCHA and was not tested.
- OCR.space ran on its public demo key. Empty Engine 3 results on Tamil, Chinese and English may be rate limiting, so we do not count them as failures. CamScanner's web Extract Text asks for a sign-in before upload, so it was not run.
- Scan: Wikimedia Commons (public domain). Text: Wikisource.
Frequently asked questions
Which free OCR tool is the most accurate?
On our test of 8 scanned pages (31 October 2026), imagetotext.info was within about a point of FastOCR on Arabic, Urdu, Hindi and Bengali. OCR.space Engine 3 matched it on Arabic, trailed on Urdu (19.6% against 9.1%) and beat it on Hindi (2.7% against 13.2%). Tesseract, the engine NewOCR says it uses, had a 55.3% character error rate on Urdu and 80.0% on Persian, against 9.1% and 10.5% for FastOCR.
What is the best free OCR tool?
It depends on the file. For a photo or screenshot with no account, FastOCR (made by the publisher of this page) takes images without sign-up or a watermark. For text from a small file inside Google Docs, use Google Drive. For a plain PDF with no registration, PDF24 is free and ad-funded. For a free API, OCR.space has a 25,000-request plan limited to 1 MB files.
Which free OCR tools need no sign-up?
FastOCR for images, PDF24 and NewOCR. Adobe's online tool runs without sign-in, but you sign in to download the searchable PDF. OnlineOCR.net allows guests 5 files an hour. Google Drive needs a Google account, and FastOCR PDFs need a free account.
Is there a free OCR tool with no watermark?
FastOCR does not add a watermark. OCR.space adds "Generated by OCR.space" to searchable PDFs on its free plan. Always open the output once to check.
Which free OCR tools read Arabic, Urdu or Hebrew?
Google Drive, PDF24, iLovePDF, i2OCR and NewOCR list Arabic, Urdu and Hebrew. OnlineOCR.net does not list them. FastOCR reads 100+ languages. Apple's built-in OCR does not support Farsi, Urdu, Hindi, Hebrew or Bengali, and Windows built-in OCR cannot read 25 of the 60 languages in FastOCR's Windows app, including Hindi, Urdu, Farsi and Thai.
What is the best free tool to OCR a PDF?
For a scanned PDF in English with no account, PDF24. For a PDF you need to search and copy from afterwards, especially Arabic, Urdu, Hebrew or Chinese, FastOCR's searchable PDF (free account, 50 pages a month). For a small file you will edit in Google Docs, Google Drive.
Can I OCR a PDF for free?
Yes, within limits. PDF24 has no stated cap, iLovePDF allows one file up to 15 MB at a time, and Google Drive takes files up to 2 MB. In FastOCR a free account includes 50 document pages a month; see the pricing page for packs and plans.
Try FastOCR
Upload an image and get the text. No registration for images. PDFs need a free account, which includes 50 document pages a month.
Open FastOCRRelated Articles & Resources
Best Arabic OCR Tools
Free Arabic OCR compared: RTL copy order, tashkeel, Urdu and mixed pages.
How to Make a PDF Searchable
Turn scanned PDFs into searchable documents.
Free OCR API Guide
Free OCR API limits, with sources.
FastOCR vs Tesseract OCR
Cloud OCR compared with the open-source engine.
FastOCR vs Adobe Acrobat OCR
How FastOCR compares with Acrobat.
English OCR Guide
Get better results on English documents.