Adobe Acrobat vs free OCR tools: Adobe OCR online and on the desktop
Short answer
How accurate is Adobe OCR compared to free tools? We did not score Acrobat, so we have no figure. Adobe OCR free online takes PDFs only and asks you to sign in to download, while text in images needs an Acrobat Pro trial. FastOCR reads images with no sign-up and returns a searchable PDF, but it does not edit PDFs.
By the FastOCR team · Updated 4 November 2026 · Accuracy test run 31 October 2026
We make FastOCR. Accuracy figures come from our own test of each tool we scored, ours included, on the same scans; other facts link to each tool's own pages. How we tested
Try it here
Drop your file here
PDF, PNG, JPG, WebP, BMP, HEIC
PDF up to 1 GB · images up to 20 MB
Tips for a clear photo
- Lay the page flat.
- Use even light, with no shadows.
- Turn off the flash to avoid glare.
- Fill the frame with the page.
Verdict
Pick FastOCR if
- You need OCR now and then and do not want an Acrobat Pro plan just for it.
- Your file is a photo or screenshot: Adobe's free online tool takes PDFs only.
- You want text, Word or Markdown beside the searchable PDF, with no sign-in for images.
- Your pages are Arabic, Urdu, Persian, Hebrew, Hindi, Bengali or Tamil, none of which is on Adobe's Export PDF language list.
Pick Adobe Acrobat if
- You edit, sign or fill PDFs as well as run OCR, which FastOCR does not do.
- You already pay for Acrobat Pro or Studio, so OCR is part of the plan.
- You process many PDFs in one run: Acrobat can recognise several files and write them to a folder you choose.
FastOCR and Adobe Acrobat side by side
| Factor | FastOCR | Adobe Acrobat |
|---|---|---|
| How you use it | FastOCRRuns in a browser tab and through a hosted API, with free offline Mac and Windows apps in public beta. | Adobe AcrobatDesktop app (All tools, Scan & OCR), plus a free online tool for PDFs.Source |
| Cost to start | FastOCRImages free with no sign-up; PDFs need a free account. See pricing. | Adobe AcrobatOCR is listed for Pro: US$19.99 a month on an annual plan billed monthly, US$29.99 month to month. Standard does not list it.Source |
| Free trial | FastOCRFree use with no time limit. | Adobe AcrobatPro shows a free-trial button; the pricing page does not give its length.Source |
| Image files (JPG, PNG) | FastOCRYes, with no sign-up; each image gets text, a one-page searchable PDF, Word and Markdown. | Adobe AcrobatThe free online tool takes PDFs; text in PNG, JPG and TIFF files is tied to the seven-day Pro trial.Source |
| Searchable PDF | FastOCRScanned PDFs and every image upload get one; Arabic and Urdu text copies out in the right order. | Adobe AcrobatYes. Recognize Text creates a searchable text layer in your PDF.Source |
| Sign-in to get the file | FastOCRNot for images. PDFs need a free account. | Adobe AcrobatThe free online tool asks you to sign in to download the searchable PDF.Source |
| Recognition languages | FastOCR100+, detected automatically, including mixed pages. | Adobe AcrobatThe Export PDF help list names 13, among them Japanese and Traditional Chinese. Arabic, Urdu, Persian, Hebrew, Hindi, Bengali and Tamil are not on it.Source |
| Picks the language for you | FastOCRYes. | Adobe AcrobatYou choose the language in the Recognize Text dialog.Source |
| Several files at once | FastOCROn paid plans, for PDFs. | Adobe AcrobatYes. In multiple files takes several PDFs and an output folder.Source |
| Edit, sign and fill PDFs | FastOCRNo. FastOCR recognises text and writes the output files. | Adobe AcrobatYes. The tool page lists editing recognized text, e-signatures and fillable forms as Pro features.Source |
| Accuracy on the six scripts shown | FastOCRFewest characters wrong, or a tie, on 6 of 6 scripts shown. Lower is better. | Adobe AcrobatNot tested |
Why FastOCR
Photos and screenshots
Every image upload gets raw text and a single-page searchable PDF, plus Word and Markdown.
See Photos and screenshotsScanned PDFs
Scanned PDF in, searchable PDF out; text copies in the right order, including right-to-left.
See Scanned PDFsLanguages
100+ languages, detected automatically, including mixed pages.
Share of characters wrong on our evidence scans (lower is better): Arabic 2.6%, Urdu 9.1%, Bengali 7.4%, Tamil 2.2%, Chinese 1.0%.
See LanguagesFree use
Images: free, no sign-up, no watermark. PDFs: free account.
See Free useOffline desktop apps
Free offline Mac and Windows apps (public beta): searchable PDF, text, Word and Markdown, nothing leaves your computer.
See Offline desktop apps
Proof
Adobe Acrobat is not in this chart; we did not run it, and Adobe publishes no error rate. On the six scripts shown the free tools below were scored, and FastOCR had the lowest or tied-lowest error rate on 6 of 6 (lower is better; gaps under 3 points count as ties).
% of characters wrong by script, lower is better
- FastOCR
- OCR.space Engine 3
- imagetotext.info
- OCR.space default Engine 2
- Tesseract 5.5.4 (the engine NewOCR says it uses)
- PDF24
- Chinese
- FastOCR 1.0%OCR.space E3: No scoreOCR.space E2 3.0%Tesseract 71.9%PDF24 3.2%
- Urdu
- FastOCR 9.1%OCR.space E3 19.6%imagetotext.info 9.2%OCR.space E2 30.4%Tesseract 55.3%PDF24 69.0%
- Bengali
- FastOCR 7.4%OCR.space E3 11.2%imagetotext.info 7.9%OCR.space E2 100.0%Tesseract 31.7%PDF24 18.6%
- Arabic
- FastOCR 2.6%OCR.space E3 2.9%imagetotext.info 2.9%OCR.space E2: Not supportedTesseract 20.4%PDF24 35.5%
- Tamil
- FastOCR 2.2%OCR.space E3: No scoreOCR.space E2 99.8%Tesseract 8.5%PDF24 9.2%
- English
- FastOCR 3.3%OCR.space E3: No scoreOCR.space E2 4.5%Tesseract 8.5%PDF24 10.1%
The scan: a page of the Urdu book Tota Kahani (written 1801)
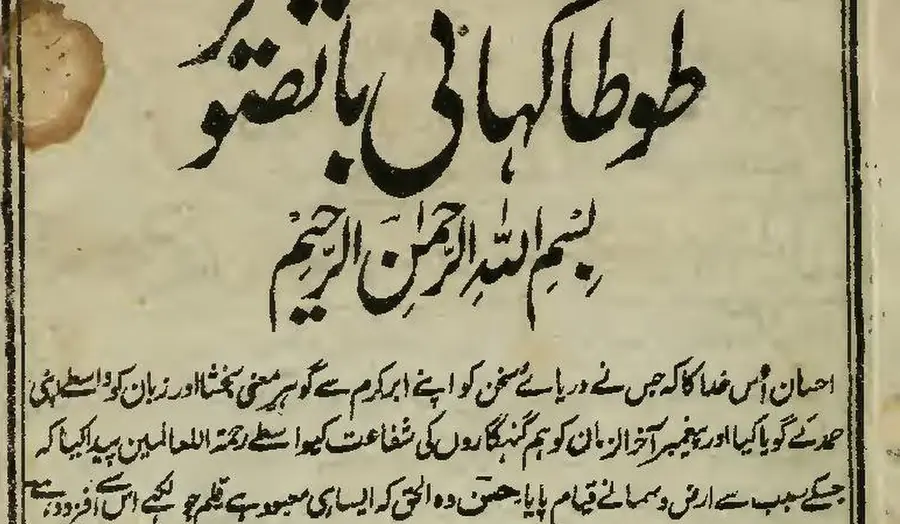
First body line, as printed (Wikisource transcription)
احسان اُس خدا کا کہ جس نے دریائے سخن کو اپنے ابر کرم سے گو ہرِ معنی بخشا اور زبان کو واسطے اپنی
- 9.1% of characters wrong
FastOCR
published by us
احسان اُس خدا کا کہ جس نے دریائے سخن کو اپنے ابر کرم سے گو ہر معنی بخشا اور زبان کو واسطے اپنی
- 9.2% of characters wrong
imagetotext.info
free web tool
احسان اُس خدا کا کہ جس نے دریائے سخن کو اپنے ابر کرم سے گو ہر معنی بخشا اور زبان کو واسطے اپنی
- 30.4% of characters wrong
OCR.space
default Engine 2
احسان أس مداكاكيج سنءريات سخن كواب ابركرم ← كوبر معى تختا اورزيان كوداسطيى
- 55.3% of characters wrong
Tesseract 5.5.4
the engine NewOCR says it uses
ا احمان اس دا اجس ےه در را سخ نکو ان ارک سےکوس ین یناد زا نک ری
- 99.6% of characters wrong
OnlineOCR.net
no Urdu option
tA)K11 tAirk.,....11.30,t4 ikitt r CIO 4 %;114iiii
How accurate is Adobe OCR compared to free tools?
There is no honest number for Adobe. We did not run Acrobat or its free online tool on our test scans, and Adobe does not publish an error rate, so any ranking of Adobe against other tools would be a guess. If accuracy decides it, put one of your own pages through both and compare the results line by line.
What we can show is how far free tools differ from each other. On our scans, a local Tesseract run got 55.3% of the Urdu page's characters wrong and 20.4% of the Arabic page, while FastOCR got 9.1% and 2.6%. Lower is better. The chart and the Urdu example below hold the full runs.
Is Adobe OCR free?
Only in part. Adobe's free online OCR tool accepts a PDF and runs text recognition, but you sign in to download the searchable result, and Adobe says the file is deleted unless you sign in to save it. The page names English, German, Spanish, French and Portuguese "and more". Making text searchable in PNG, JPG or TIFF files is described under a seven-day Acrobat Pro trial. Checked 4 November 2026.
On the desktop, Adobe's pricing page lists "Turn scans into editable PDFs" for Acrobat Pro and Studio and leaves it off Acrobat Standard. Acrobat Pro costs US$19.99 a month on an annual plan billed monthly and US$29.99 month to month. The page shows a free-trial button for Pro without saying how long the trial runs.
FastOCR takes the other route. Images are free with no sign-up and no watermark, and each one comes back as text, a one-page searchable PDF, Word and Markdown. A scanned PDF needs a free account, and the pricing page shows what the free and paid plans include.
Which languages does Adobe OCR support?
More than English. Adobe's language help page for Acrobat Export PDF names English (US and UK), Danish, Dutch, Spanish, French, Japanese, Russian, Italian, Traditional Chinese, Norwegian, Portuguese, Finnish and Swedish. It tells you to pick the language before you run OCR on Japanese, Chinese or Korean pages. It does not list Arabic, Urdu, Persian, Hebrew, Hindi, Bengali, Tamil or Thai.
That is a gap in what Adobe documents, not a test result. The page covers Export PDF, so the Recognize Text dialog in the desktop app may offer more, and we did not install Acrobat to check. For a script that is not listed, run one page first. The language and plan breakdown goes through each Acrobat plan.
FastOCR picks the language of each page by itself, so a mixed Urdu and English letter needs no setting. On our scans it got 9.1% of Urdu characters wrong, 2.6% of Arabic and 2.2% of Tamil; lower is better.
Making a scanned PDF searchable
In Acrobat, open the scanned PDF, choose All tools, then Scan & OCR, then In this file. Set the page range and language, and select Recognize Text. Adobe's help page says Acrobat then creates a searchable text layer in the PDF. For a pile of files, In multiple files takes several PDFs and writes the processed copies to a folder.
FastOCR does the same job in a browser tab. A scanned PDF keeps its page image and gains an invisible text layer, and the text copies out in reading order, right-to-left scripts included. Sign in with a free account for PDFs; images need none.
Acrobat edits PDFs; FastOCR does not
Adobe's online tool page lists editing recognized text, e-signatures and fillable forms as Acrobat Pro features. If you need to change words on a page, sign it or fill a form, that is Acrobat's job, and FastOCR will not replace it. FastOCR reads a document and writes text, a searchable PDF, Word and Markdown.
For small PDF jobs the free browser PDF tools merge, split, compress and sign, and the files stay in the browser.
Offline: Acrobat or the free FastOCR apps
If you want to recognise text on your own computer without a yearly plan, the free Mac and Windows apps from FastOCR work offline and save a searchable PDF, text, Word or Markdown. They use Apple Vision and Windows OCR, so none of the figures on this page describe them. Both are unsigned public betas, and your system warns you the first time you open one.
They are not PDF editors. Acrobat stays the better desktop choice when OCR is one step in a longer PDF workflow.
Choose Adobe Acrobat if
- You edit, sign or fill PDFs as well as run OCR; Adobe's tool page lists those under Acrobat Pro.
- You already pay for Acrobat Pro or Studio, so OCR costs nothing extra and one app covers the rest.
- You recognise many PDFs in one run: Recognize Text takes several files and writes them to a folder you choose.
- Your pages are in a language on the Export PDF list, such as Japanese or Traditional Chinese, and you would rather stay in one app.
FAQ
Is there a free alternative to Adobe Acrobat OCR?
Yes. FastOCR reads images with no sign-up and no watermark, and a scanned PDF becomes a searchable PDF with a free account. You also get text, Word and Markdown. It does not edit, sign or fill PDFs, so Acrobat stays ahead for that.
How accurate is Adobe OCR compared to free tools?
We did not score Adobe, so there is no figure. Across the six scripts shown FastOCR had the lowest or tied-lowest error rate on 6 of 6. Lower is better. Try your own file in both.
Do I need Acrobat Pro to OCR a scanned PDF?
For Acrobat's desktop OCR, Adobe's pricing page lists "Turn scans into editable PDFs" for Pro and Studio, not Standard. Adobe's free online tool also makes a PDF searchable, but you sign in to download it. FastOCR needs a free account for PDFs.
Does Adobe OCR support Arabic or Urdu?
Adobe's Export PDF language list does not name Arabic, Urdu, Persian, Hebrew, Hindi, Bengali or Tamil. That is advertised, not tested, and the desktop dialog may offer more. FastOCR detects those languages itself; test one page of yours first.
Can Adobe OCR read JPG and PNG images?
Adobe's free online tool takes PDFs. Its page ties text recognition in PNG, JPG and TIFF files to the seven-day Acrobat Pro trial. FastOCR reads image files directly and returns text and a one-page searchable PDF without an account.
Does FastOCR keep the scan and add a text layer?
Yes. The searchable PDF shows the scanned page as it looked and adds an invisible text layer, so search and copy work. Right-to-left text copies out in order. PDFs use your page allowance; images do not need an account.
Can FastOCR edit or sign PDFs like Acrobat?
No. FastOCR recognises text and writes text, a searchable PDF, Word and Markdown. Its free browser PDF tools merge, split, compress and sign, but they do not change the words on a page. Use Acrobat to edit text.
Method
Adobe facts come from Adobe's own pages, re-read on 4 November 2026: the Acrobat pricing page, the free online OCR tool page, the Recognize Text help page (updated 22 October 2026) and the Export PDF OCR language list (updated 30 April 2026). We did not run Acrobat or Adobe's online tool, so every statement about them is documentation, and anything Adobe does not state is shown as Not stated, never as No. The accuracy figures for the other tools are from our free-tool test of 31 October 2026: one public-domain scanned page per script, scored as the share of characters wrong against the Wikisource text, so lower is better. FastOCR's outputs date from 25 October 2026.
Change log
- 27 June 2026: First published.
- 1 November 2026: Rewritten with sourced Adobe facts and a free-tool accuracy table.
- 4 November 2026: Moved to the comparison template. Added the free online tool, desktop plan, language and image-file answers, re-read from Adobe.