Best Urdu OCR Tools in 2026, Tested on a Real Scan (اردو OCR)
Short answer
For an Urdu scanner you can use from a browser, two tools finished level on our Nastaliq page: FastOCR (we make it) got 9.1% of characters wrong and imagetotext.info 9.2%; lower is better. OCR.space Engine 3 got 19.6% and Tesseract 55.3%. i2OCR Urdu is untested because it asks for a CAPTCHA.
By the FastOCR team · Updated 4 November 2026 · Accuracy test run 31 October 2026
We make FastOCR. Accuracy figures come from our own test of each tool we scored, ours included, on the same scans; other facts link to each tool's own pages. How we tested
Try it here
Drop your file here
PDF, PNG, JPG, WebP, BMP, HEIC
PDF up to 1 GB · images up to 20 MB
Tips for a clear photo
- Lay the page flat.
- Use even light, with no shadows.
- Turn off the flash to avoid glare.
- Fill the frame with the page.
Verdict
Pick FastOCR if
- You have a scanned Urdu PDF or a photo and need a searchable PDF whose Urdu copies and searches right to left.
- You want Word or Markdown from an Urdu image, or an English translation of a finished one.
- You want to try Urdu with no account and no watermark, and send pages from code if it works.
Pick another tool if
- You only need plain text from one Urdu image: imagetotext.info got 9.2% wrong to FastOCR's 9.1%, level inside the noise (lower is better).
- You work in Google Docs and your file is small and simple: its help page lists Urdu.
- You want one Urdu page at a time, deleted fast, from a tool with an Urdu-specific page: i2OCR.
- You want an offline engine to script and will tune it yourself: Tesseract, though it scored far behind here.
Best for
- Scanned Urdu PDFs and photos you will search and copy from: FastOCROur tool
Every image gets text, a searchable PDF whose Urdu is written in reading order, Word and Markdown, with no sign-up. It got 9.1% of our Nastaliq page wrong (lower is better).
- One Urdu image to plain text, no account: imagetotext.info
9.2% of the Nastaliq page wrong, level with FastOCR inside the noise (lower is better). Its page does not ask you to register, and its home page does not name Urdu.Our test
- A free Urdu API to prototype with:
- An Urdu page you want read by an Urdu-specific page, deleted fast:
- A small, simple file you will edit in Google Docs: Google Drive
Its help page lists Urdu and asks for files of 2 MB or smaller, right side up.Source
- A scanned PDF inside a PDF toolkit you already use:
- Many images with no account and no stated file count limit:
- An offline engine you script yourself:
Comparison table
| Tool | Urdu page, % of characters wrong (lower is better) | Urdu on its language list | Free without sign-up | Outputs |
|---|---|---|---|---|
| FastOCR (our tool)Our tool | Urdu page, % of characters wrong (lower is better)9.1% | Urdu on its language listDetected automatically | Free without sign-upImages: yes. PDFs: free account. | OutputsText, searchable PDF, Word, Markdown |
| imagetotext.info | Urdu page, % of characters wrong (lower is better)9.2%Our test | Urdu on its language listNot named on its home pageSource | Free without sign-upYes, no registrationSource | OutputsText, Word, HTML, MarkdownSource |
| OCR.space | Urdu page, % of characters wrong (lower is better)Engine 3: 19.6%. Default Engine 2: 30.4%.Our test | Urdu on its language listNot named on its language tableSource | Free without sign-upYes, no registrationSource | OutputsText, JSON, searchable PDF (watermarked on the free API)Source |
| Tesseract | Urdu page, % of characters wrong (lower is better)55.3%Our test | Urdu on its language listUrdu data fileSource | Free without sign-upOpen source; you install itSource | OutputsText, hOCR, PDF, TSV, ALTOSource |
| PDF24 | Urdu page, % of characters wrong (lower is better)69.0%Our test | Urdu on its language listListed; you pick it by handSource | Free without sign-upYes, no registrationSource | OutputsSearchable PDF or PDF/ASource |
| OnlineOCR.net | Urdu page, % of characters wrong (lower is better)99.6% (English selected; it came back as Latin letters)Our test | Urdu on its language listDoes not list UrduSource | Free without sign-upGuests: yes, 5 files an hourSource | OutputsText, Word, ExcelSource |
| i2OCR | Urdu page, % of characters wrong (lower is better)Not tested | Urdu on its language listListed, with its own Urdu pageSource | Free without sign-upNot statedSource | OutputsText, Word, PDF, searchable PDFSource |
| Google Drive | Urdu page, % of characters wrong (lower is better)Not tested | Urdu on its language listListedSource | Free without sign-upWorks inside your Google DriveSource | OutputsA Google DocSource |
| iLovePDF | Urdu page, % of characters wrong (lower is better)Not tested | Urdu on its language listListedSource | Free without sign-upNot statedSource | OutputsSearchable PDFSource |
| NewOCR | Urdu page, % of characters wrong (lower is better)Not tested | Urdu on its language listListedSource | Free without sign-upYes, no registrationSource | OutputsTXT, DOC, PDFSource |
| ABBYY FineReader | Urdu page, % of characters wrong (lower is better)Not tested | Urdu on its language listLists Arabic; Urdu not on the specifications pageSource | Free without sign-upNot statedSource | OutputsSearchable PDF and document formatsSource |
Why FastOCR
Scanned PDFs
Scanned PDF in, searchable PDF out; text copies in the right order, including right-to-left.
See Scanned PDFsPhotos and screenshots
Every image upload gets raw text and a single-page searchable PDF, plus Word and Markdown.
See Photos and screenshotsLanguages
100+ languages, detected automatically, including mixed pages.
Share of characters wrong on our evidence scans (lower is better): Arabic 2.6%, Urdu 9.1%, Bengali 7.4%, Tamil 2.2%, Chinese 1.0%.
See LanguagesFree use
Images: free, no sign-up, no watermark. PDFs: free account.
See Free useTranslation and AI Polish
Translate or clean up the text of a finished image.
See Translation and AI Polish
Proof
On one Nastaliq page FastOCR (9.1% of characters wrong) and imagetotext.info (9.2%) finished level inside the noise. OCR.space Engine 3 got 19.6%, Engine 2 30.4%, Tesseract 55.3% and PDF24 69.0%. Lower is better.
The scan: a page of the Urdu book Tota Kahani (written 1801)
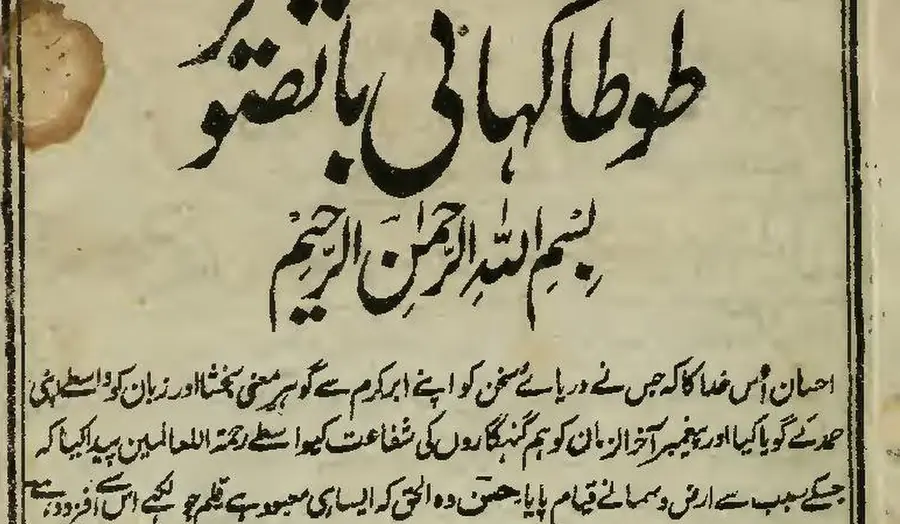
First body line, as printed (Wikisource transcription)
احسان اُس خدا کا کہ جس نے دریائے سخن کو اپنے ابر کرم سے گو ہرِ معنی بخشا اور زبان کو واسطے اپنی
- 9.1% of characters wrong
FastOCR
published by us
احسان اُس خدا کا کہ جس نے دریائے سخن کو اپنے ابر کرم سے گو ہر معنی بخشا اور زبان کو واسطے اپنی
- 9.2% of characters wrong
imagetotext.info
free web tool
احسان اُس خدا کا کہ جس نے دریائے سخن کو اپنے ابر کرم سے گو ہر معنی بخشا اور زبان کو واسطے اپنی
- 30.4% of characters wrong
OCR.space
default Engine 2
احسان أس مداكاكيج سنءريات سخن كواب ابركرم ← كوبر معى تختا اورزيان كوداسطيى
- 55.3% of characters wrong
Tesseract 5.5.4
the engine NewOCR says it uses
ا احمان اس دا اجس ےه در را سخ نکو ان ارک سےکوس ین یناد زا نک ری
- 99.6% of characters wrong
OnlineOCR.net
no Urdu option
tA)K11 tAirk.,....11.30,t4 ikitt r CIO 4 %;114iiii
% of characters wrong by script, lower is better
- FastOCR
- OCR.space Engine 3
- imagetotext.info
- OCR.space default Engine 2
- Tesseract 5.5.4 (the engine NewOCR says it uses)
- PDF24
- Chinese
- FastOCR 1.0%OCR.space E3: No scoreOCR.space E2 3.0%Tesseract 71.9%PDF24 3.2%
- Urdu
- FastOCR 9.1%OCR.space E3 19.6%imagetotext.info 9.2%OCR.space E2 30.4%Tesseract 55.3%PDF24 69.0%
- Bengali
- FastOCR 7.4%OCR.space E3 11.2%imagetotext.info 7.9%OCR.space E2 100.0%Tesseract 31.7%PDF24 18.6%
- Arabic
- FastOCR 2.6%OCR.space E3 2.9%imagetotext.info 2.9%OCR.space E2: Not supportedTesseract 20.4%PDF24 35.5%
- Tamil
- FastOCR 2.2%OCR.space E3: No scoreOCR.space E2 99.8%Tesseract 8.5%PDF24 9.2%
- English
- FastOCR 3.3%OCR.space E3: No scoreOCR.space E2 4.5%Tesseract 8.5%PDF24 10.1%
The result: one Urdu page through six tools
The page comes from Tota Kahani, an Urdu book from 1801, in a public-domain scan. The score is the share of characters a tool got wrong, so lower is better. FastOCR scored 9.1% and imagetotext.info 9.2%; the reference text itself is off by 1% to 6%, so that is a tie.
The rest of the field, lower is better:
- OCR.space Engine 3: 19.6%; its default Engine 2: 30.4%.
- Tesseract 5.5.4 with its Urdu pack: 55.3%.
- PDF24 with Urdu picked by hand: 69.0%.
- OnlineOCR.net: 99.6%, because it has no Urdu setting and returned Latin letters.
imagetotext.info's home page says it is powered by tesseract-ocr, yet it scored far better than our own Tesseract run, so we do not know what happens inside it and do not guess. One page is a spot check, and an 1801 book is not a newspaper or a phone photo.
If you searched for i2OCR Urdu: its Urdu page describes an Urdu-optimized model, but the site asks for a CAPTCHA, so we have no score for it and make no claim about it.
Why Urdu is harder than Arabic
Every tool that read both our Arabic and Urdu pages did worse on Urdu. FastOCR went from 2.6% on Arabic to 9.1% on Urdu, Tesseract from 20.4% to 55.3%, and PDF24 from 35.5% to 69.0%. Lower is better.
Urdu uses the Arabic letters plus some of its own. The larger change is the print style: most Arabic print is Naskh, an upright style, and most Urdu is Nastaliq, a sloping one. A tool tuned on Arabic print meets a different shape.
The Nastaliq challenge (نستعلیق)
Four things make Nastaliq hard for a machine:
- No flat baseline. Words slope down toward the left, so line finding that expects a straight line can split or merge lines.
- Tight clusters. Letters join and stack, so it is unclear where one ends and the next begins.
- Dots decide the letter. Several letters differ only by their dots, and a missed dot gives a different, often real, word.
- Many fonts. Books and newspapers use different Nastaliq faces, and a model that has seen few of them makes more errors.
Urdu in a searchable PDF and in Word
A searchable PDF puts invisible text over the scan. FastOCR writes that layer in reading order for Urdu, so a pasted line starts with its first word and Ctrl+F finds what you see. Viewers differ: Chrome's built-in viewer can scramble Latin letters and brackets inside a right-to-left line even when the file is right, so check a second viewer before blaming the file.
The Word download marks Urdu paragraphs as right-to-left, so lines run from the right in Word. We do not claim it keeps the page layout.
1. FastOCR (our tool)
- Best for
- Urdu images and scanned PDFs that must come back as a searchable PDF, Word or Markdown.
- Watch out for
- Guests have a daily image cap, PDFs need a free account, and we did not test handwriting.
FastOCR reads Urdu photos, screenshots and scans and detects the language itself, so there is no menu to set. Images need no account and get no watermark. You get raw text, a one-page searchable PDF, Word and Markdown. Start on the Urdu OCR page.
A scanned PDF comes back as a searchable PDF with the text layer in reading order, once you have a free account. A finished Urdu image can be translated or cleaned up with AI Polish; neither works on PDFs. For code there is a REST API, Python SDK and MCP server.
In our test: 9.1% of the Nastaliq page's characters wrong, level with imagetotext.info (9.2%) inside the noise and well ahead of OCR.space Engine 3 (19.6%). Lower is better.
2. imagetotext.info
- Best for
- One Urdu image to text, Word or Markdown with no account.
- Watch out for
- No searchable PDF is listed, its home page does not name Urdu, and several files at once need an upgrade.
imagetotext.info exports text, Word, HTML and Markdown, and its page tells visitors they are not asked to register. The language sentence on its home page names 23 languages and Urdu is not among them.
In our test: 9.2% of the Urdu page's characters wrong against FastOCR's 9.1%, a tie inside the noise (lower is better).
Source: imagetotext.info, checked 4 November 2026. Compare: FastOCR vs imagetotext.info.
3. OCR.space
- Best for
- Developers who want a free API to try Urdu on short text.
- Watch out for
- Urdu is not named on its language table, free API files are capped at 1 MB and 3 PDF pages, and free searchable PDFs are watermarked.
The OCR.space web tool is free without registration, with a 5 MB cap on each document. Its API page lists the free plan at 1 MB files and 3 PDF pages, with searchable PDFs marked "with watermark".
In our test: Urdu is missing from its language table, but both engines read our page. Engine 3 got 19.6% of the characters wrong and the default Engine 2 30.4%, on a public demo key. Lower is better.
Source: OCR.space API, checked 4 November 2026. Compare: FastOCR vs OCR.space.
4. Tesseract (open source)
- Best for
- Developers who want a local engine and will tune it for Nastaliq.
- Watch out for
- It got over half of our Nastaliq page wrong, and it has no window to click.
Tesseract is free, open-source OCR that runs on your own computer, so no file leaves it. It has an Urdu data file and writes text, hOCR, PDF, TSV and ALTO.
In our test: version 5.5.4 with the Urdu pack got 55.3% of the page's characters wrong. It is a fair tool on clean English, but Nastaliq needs more work than the tools above. Lower is better.
Source: Tesseract data files, checked 4 November 2026. Compare: FastOCR vs Tesseract.
5. PDF24 OCR
- Best for
- A scanned PDF made searchable for free with no registration, when the text is not Nastaliq.
- Watch out for
- It scored furthest behind of the working tools on our Urdu page.
PDF24 is free with no registration, funded by advertising, and deletes files after an hour. You choose Urdu from its language menu, and the result is a searchable PDF or PDF/A.
In our test: with Urdu picked by hand it got 69.0% of the page's characters wrong. Lower is better.
Source: PDF24 OCR, checked 4 November 2026. Compare: FastOCR vs PDF24.
6. OnlineOCR.net
- Best for
- Latin-script pages; it is not an Urdu tool.
- Watch out for
- Its 46 recognition languages do not include Urdu.
OnlineOCR.net lets guests convert 5 files an hour up to 15 MB. Its language menu has no Urdu, Arabic or Persian.
In our test: with its default English setting our Urdu page came back as Latin letters, 99.6% wrong. Lower is better.
Source: OnlineOCR.net, checked 4 November 2026. Compare: FastOCR vs OnlineOCR.net.
7. i2OCR for Urdu
- Best for
- One Urdu page at a time that you want deleted within 30 minutes.
- Watch out for
- The free version does one image per run, and there is no score here because of its CAPTCHA.
i2OCR has a page just for Urdu. It says it uses an Urdu-optimized model for printed Nastaliq and Naskh text, and that the free version processes one image per run while bulk OCR is premium. Its FAQ allows images up to 20 MB and says outputs are removed within 30 minutes. It does not name its engine, so we will not guess one.
In our test: not run. Try the same page there and on FastOCR and compare the pasted lines. Source: i2OCR Urdu, checked 4 November 2026.
8. Google Drive and Docs
- Best for
- A quick free try if you already use Google.
- Watch out for
- You get a Google Doc, not a searchable PDF, and it needs a Google account.
Open a PDF or a .jpeg, .png or .gif photo with Google Docs to get its text. The help page lists Urdu, wants text at least 10 pixels high, and says tables and columns are not likely to be detected. We did not test it, so we give no figure.
Source: Google Drive Help, checked 4 November 2026. Compare: FastOCR vs Google Drive OCR.
9. iLovePDF OCR PDF
- Best for
- Urdu PDFs when you already work in iLovePDF.
- Watch out for
- The free plan is described without numbers, and it was outside our accuracy run.
iLovePDF makes a searchable PDF and lists Urdu among its document languages. Its free plan is described as limited document processing.
Source: iLovePDF OCR PDF, checked 4 November 2026. Compare: FastOCR vs iLovePDF.
10. NewOCR
- Best for
- Many Urdu images with no account.
- Watch out for
- It sits behind a CAPTCHA, so it was not run, and no file size limit is published.
NewOCR says it needs no registration, has no limit on the number of files and supports 122 languages including Urdu. Its page says the service is based on the Tesseract OCR engine, so our Tesseract run is the nearest evidence, and it scored poorly.
Source: NewOCR, checked 4 November 2026.
11. ABBYY FineReader PDF
- Best for
- Teams that already pay for ABBYY and confirm Urdu with the vendor first.
- Watch out for
- Paid software, and the specifications page we read does not list Urdu.
ABBYY FineReader PDF 16 claims 198 recognition languages. We looked for Urdu on its specifications page and did not find it, while Arabic is listed. That may be a gap in the page and not in the product, so ask before buying. We did not test it.
Source: ABBYY specifications, checked 4 November 2026. Compare: FastOCR vs ABBYY FineReader.
Tips for better Urdu OCR
We did not measure these; each is cheap to try:
- Keep the page straight and fix a tilted photo before you upload.
- Use a sharp image with even light, and crop out shadows, fingers and desk.
- Check a few lines against the page, because a missed dot gives a real but wrong word.
- For a PDF, copy a line first: if it pastes as clean Urdu, the file already has text.
Which Urdu job needs which tool
- A scanned Urdu book or notice as a PDF: use FastOCR for a searchable PDF; the Urdu PDF to text page has the steps.
- One photo, text only: Urdu image to text or imagetotext.info.
- Handwritten Urdu: we did not test it; see Urdu handwriting OCR and expect to proofread.
- A developer prototype: OCR.space has a free API with small limits, and FastOCR has an OCR API.
- Arabic text, not Urdu: see best Arabic OCR tools.
How we tested
- Run dates: the production API produced FastOCR's output on 25 October 2026, and the rest ran on 31 October 2026. Vendor facts were checked on 4 November 2026. Re-run this test before quoting the numbers after January 2027.
- Page: one scanned page of Tota Kahani from Wikimedia Commons, scored against its Wikisource transcription.
- Score: spaces, punctuation and Arabic diacritics are stripped, then we count the share of characters wrong (lower is better). The Wikisource text and our own proofread key differ by 1% to 6%, so gaps under about 3 points are noise.
- FastOCR got a 500-pixel-wide image; the other tools got 1,280 pixels.
- Tesseract 5.5.4 ran locally with the Urdu pack. OCR.space ran on its public demo key. PDF24 ran with Urdu chosen by hand. OnlineOCR.net ran with its default English setting because it has no Urdu option.
- i2OCR is behind a CAPTCHA. Google Drive, iLovePDF, NewOCR and ABBYY were not run.
- One page is a small sample. Newspapers, phone photos and handwriting were not tested.
When another tool is the better choice
- You need plain text from one Urdu image and nothing else: imagetotext.info scored level with FastOCR (9.2% against 9.1%, lower is better).
- You work in Google Docs and your Urdu file is small and simple.
- You want a free API for a prototype: OCR.space, with 1 MB files and 3 PDF pages.
- You want an Urdu-specific page and can pass a CAPTCHA each run: i2OCR.
FAQ
Is there a free Urdu OCR tool?
Yes. FastOCR reads Urdu images in the browser with no account and no watermark, and scanned PDFs need a free account. imagetotext.info got 9.2% of our Urdu page wrong to FastOCR's 9.1%, so it is a fair free choice for a single image (lower is better).
What is the best Urdu OCR?
On one Nastaliq page FastOCR got 9.1% of characters wrong and imagetotext.info 9.2%, a tie because the reference text is off by 1% to 6%. OCR.space Engine 3 followed at 19.6%. It is one page, so treat it as a guide. Lower is better.
Does i2OCR work for Urdu?
i2OCR has an Urdu page and says it uses an Urdu-optimized model and removes outputs within 30 minutes. The free version handles one image per run. We could not score it because it asks for a CAPTCHA, so we give no accuracy figure for it.
How do I extract Urdu text from a PDF?
Upload the scanned PDF to FastOCR with a free account and download the text or the searchable PDF. If you can already select and copy clean Urdu from your PDF, it has a text layer and you may not need OCR. Copy a few lines first.
Can I convert an Urdu PDF to Word?
Yes. FastOCR exports a finished result as a Word file that marks Urdu paragraphs as right-to-left, so lines run from the right. We do not claim it keeps the page layout, so check tables and columns.
Will Urdu copy from a searchable PDF in the right order?
FastOCR writes the invisible text layer in reading order, so a pasted Urdu line starts with its first word. Chrome's viewer can scramble Latin letters and brackets inside a right-to-left line, so try a second viewer. Pure Urdu lines are not affected.
What is the difference between Naskh and Nastaliq?
Naskh is the upright style used in most Arabic print. Nastaliq is the sloping style used for most Urdu, with words that slope down to the left and letters in tight clusters. Every tool that read both our pages did worse on Urdu.
Can OCR read handwritten Urdu?
We did not test handwriting, so we make no claim about it. Our test used a printed book page. See the Urdu handwriting page for what FastOCR does, and expect to proofread any handwritten result.
Method
Each vendor fact links to that tool's own page, checked 4 November 2026; where a page is silent we write Not stated, never No. Accuracy is the share of characters wrong against the Wikisource text, lower is better, on one Nastaliq page run on 31 October 2026. Six tools were run; details are in how we tested.
Change log
- 1 February 2026: First published.
- 1 November 2026: Added the Nastaliq test page scored on six tools.
- 4 November 2026: Rebuilt on the shared comparison format with vendor pages re-read, and added iLovePDF and NewOCR.