Best OCR Tools for Students: Free OCR Software for School in 2026
Short answer
The best OCR tools for education depend on the job. Google Lens copies one slide from your camera, and Google Drive turns a scanned PDF into a Google Doc. FastOCR (we make it) reads lecture-note photos, textbook pages and scanned PDFs, Arabic and Urdu included, and writes ruled tables into Word. Handwriting was not measured.
By the FastOCR team · Updated 4 November 2026 · Accuracy test run 31 October 2026
We make FastOCR. Accuracy figures come from our own test of each tool we scored, ours included, on the same scans; other facts link to each tool's own pages. How we tested
Try it here
Drop your file here
PDF, PNG, JPG, WebP, BMP, HEIC
PDF up to 1 GB · images up to 20 MB
Tips for a clear photo
- Lay the page flat.
- Use even light, with no shadows.
- Turn off the flash to avoid glare.
- Fill the frame with the page.
Verdict
Pick FastOCR if
- Your course material is in Urdu or Arabic. On our Urdu page FastOCR got 9.1% of characters wrong and Tesseract 55.3%; lower is better.
- You have a scanned textbook or past paper as a PDF and want a searchable PDF, or text and Word files for your notes.
- A handout holds a ruled table, which the Word download rebuilds as a real Word table, right to left for Arabic.
Pick another tool if
- You want one slide or a paragraph the moment you see it: Google Lens on your phone.
- The file already sits in Google Drive and a Google Doc is the result you want: Google Drive.
- Your notes live in OneNote, where Copy Text from Picture is built in.
Best for
- Urdu or Arabic study material: FastOCROur tool
On the Urdu page FastOCR got 9.1% of characters wrong and imagetotext.info 9.2%, a gap inside the noise; on Arabic it was 2.6% against 2.9%. Lower is better.
- A scanned textbook or past paper, in a searchable PDF or Word file: FastOCROur tool
Upload the PDF or the page photos and download text, a searchable PDF, Word or Markdown. PDFs need a free account; images do not.
- A ruled table in an Arabic or English handout: FastOCROur tool
The Word download rebuilds tables drawn with a line around every cell; tables without lines come back as lines of text.
- One slide, quickly, from your camera: Google Lens
Google describes Lens as a way to copy text from the world around you and translate signs, menus and handwriting in over 100 languages.Source
- A PDF or photo in Google Drive, as a Google Doc: Google Drive
Google says to right-click the file and choose Open with Google Docs, for files of 2 MB or smaller; lists, tables and columns are not likely to be detected.Source
- Notes you already keep in OneNote: Microsoft OneNote
Right-click a picture and choose Copy Text from Picture; Microsoft warns some results can take 24 to 48 hours.Source
- Free offline OCR on your own computer, from a terminal:
Comparison table
| Tool | Free use, as advertised | What you get back | Urdu, share of characters wrong (lower is better) | Arabic, share of characters wrong (lower is better) | English, share of characters wrong (lower is better) |
|---|---|---|---|---|---|
| FastOCR (our tool)Our tool | Free use, as advertisedFree for images: no account, no watermark. PDFs need a free account. | What you get backText, searchable PDF, Word, Markdown | Urdu, share of characters wrong (lower is better)9.1% | Arabic, share of characters wrong (lower is better)2.6% | English, share of characters wrong (lower is better)3.3% |
| imagetotext.info | Free use, as advertisedFree for a single upload; several files need a paid planSource | What you get backText; Word, HTML and Markdown controlsSource | Urdu, share of characters wrong (lower is better)9.2%Our test | Arabic, share of characters wrong (lower is better)2.9%Our test | English, share of characters wrong (lower is better)Not tested |
| OCR.space | Free use, as advertisedWeb tool: 5 MB per document, no sign-upSource | What you get backText, searchable PDF, MarkdownSource | Urdu, share of characters wrong (lower is better)19.6% (Engine 3)Our test | Arabic, share of characters wrong (lower is better)2.9% (Engine 3)Our test | English, share of characters wrong (lower is better)Not scored: empty resultsOur test |
| Tesseract | Free use, as advertisedFree, runs on your computerSource | What you get backText, searchable PDFSource | Urdu, share of characters wrong (lower is better)55.3%Our test | Arabic, share of characters wrong (lower is better)20.4%Our test | English, share of characters wrong (lower is better)8.5%Our test |
| PDF24 | Free use, as advertisedFree, no sign-in, paid for by adsSource | What you get backSearchable PDFSource | Urdu, share of characters wrong (lower is better)69.0%Our test | Arabic, share of characters wrong (lower is better)35.5%Our test | English, share of characters wrong (lower is better)10.1%Our test |
| Smallpdf | Free use, as advertisedThe free plan has a daily download limitSource | What you get backSearchable PDF, WordSource | Urdu, share of characters wrong (lower is better)Not scored: out of free downloadsOur test | Arabic, share of characters wrong (lower is better)99.1%Our test | English, share of characters wrong (lower is better)Not scored: out of free downloadsOur test |
| OnlineOCR.net | Free use, as advertisedGuests: 5 files an hour; sign-up adds a 50-page allowanceSource | What you get backText, Word, Excel, PDF, RTFSource | Urdu, share of characters wrong (lower is better)99.6% (no Urdu option; Latin letters came back)Our test | Arabic, share of characters wrong (lower is better)Does not list ArabicSource | English, share of characters wrong (lower is better)Not tested |
| Google Lens | Free use, as advertisedNot statedSource | What you get backCopied text, translationSource | Urdu, share of characters wrong (lower is better)Not tested | Arabic, share of characters wrong (lower is better)Not tested | English, share of characters wrong (lower is better)Not tested |
| Google Drive | Free use, as advertisedFiles of 2 MB or smaller; text at least 10 pixels highSource | What you get backA Google DocSource | Urdu, share of characters wrong (lower is better)Not tested | Arabic, share of characters wrong (lower is better)Not tested | English, share of characters wrong (lower is better)Not tested |
| Adobe Acrobat online | Free use, as advertisedSign-in needed to download the searchable PDFSource | What you get backSearchable PDFSource | Urdu, share of characters wrong (lower is better)Not tested | Arabic, share of characters wrong (lower is better)Not tested | English, share of characters wrong (lower is better)Not tested |
| Adobe Scan | Free use, as advertisedFree to downloadSource | What you get backSearchable PDF, JPEGSource | Urdu, share of characters wrong (lower is better)Not tested | Arabic, share of characters wrong (lower is better)Not tested | English, share of characters wrong (lower is better)Not tested |
| Microsoft OneNote | Free use, as advertisedNot statedSource | What you get backText you paste from the pictureSource | Urdu, share of characters wrong (lower is better)Not tested | Arabic, share of characters wrong (lower is better)Not tested | English, share of characters wrong (lower is better)Not tested |
Why FastOCR
Photos and screenshots
Every image upload gets raw text and a single-page searchable PDF, plus Word and Markdown.
See Photos and screenshotsScanned PDFs
Scanned PDF in, searchable PDF out; text copies in the right order, including right-to-left.
See Scanned PDFsLanguages
100+ languages, detected automatically, including mixed pages.
Share of characters wrong on our evidence scans (lower is better): Arabic 2.6%, Urdu 9.1%, Bengali 7.4%, Tamil 2.2%, Chinese 1.0%.
See LanguagesExports
Raw text, Word (.docx) and Markdown.
See ExportsFree use
Images: free, no sign-up, no watermark. PDFs: free account.
See Free use
Proof
Google Lens, Google Drive, OneNote and Adobe were not run on our scans. On the six scripts shown, FastOCR got 9.1% of the Urdu page's characters wrong, imagetotext.info 9.2%, OCR.space Engine 3 19.6% and Tesseract 55.3%; lower is better. imagetotext.info tied FastOCR on Urdu and Arabic.
The scan: a page of the Urdu book Tota Kahani (written 1801)
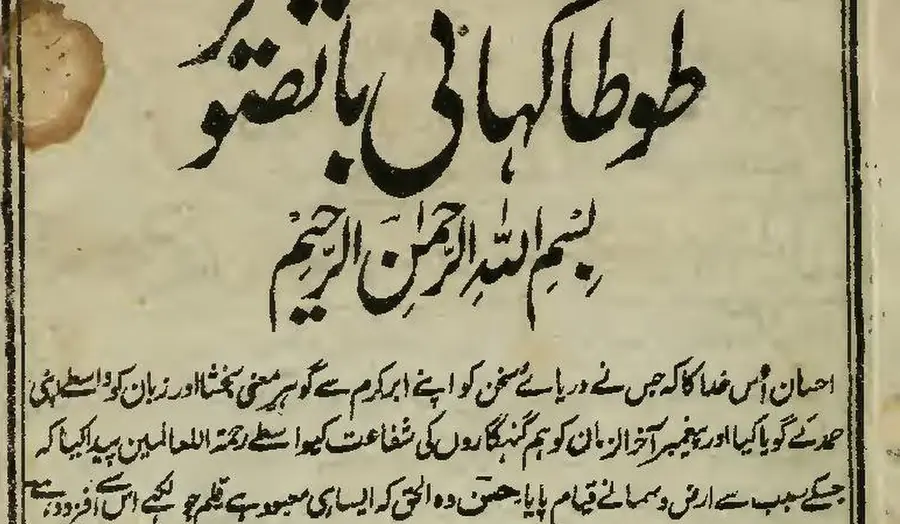
First body line, as printed (Wikisource transcription)
احسان اُس خدا کا کہ جس نے دریائے سخن کو اپنے ابر کرم سے گو ہرِ معنی بخشا اور زبان کو واسطے اپنی
- 9.1% of characters wrong
FastOCR
published by us
احسان اُس خدا کا کہ جس نے دریائے سخن کو اپنے ابر کرم سے گو ہر معنی بخشا اور زبان کو واسطے اپنی
- 9.2% of characters wrong
imagetotext.info
free web tool
احسان اُس خدا کا کہ جس نے دریائے سخن کو اپنے ابر کرم سے گو ہر معنی بخشا اور زبان کو واسطے اپنی
- 30.4% of characters wrong
OCR.space
default Engine 2
احسان أس مداكاكيج سنءريات سخن كواب ابركرم ← كوبر معى تختا اورزيان كوداسطيى
- 55.3% of characters wrong
Tesseract 5.5.4
the engine NewOCR says it uses
ا احمان اس دا اجس ےه در را سخ نکو ان ارک سےکوس ین یناد زا نک ری
- 99.6% of characters wrong
OnlineOCR.net
no Urdu option
tA)K11 tAirk.,....11.30,t4 ikitt r CIO 4 %;114iiii
% of characters wrong by script, lower is better
- FastOCR
- OCR.space Engine 3
- imagetotext.info
- OCR.space default Engine 2
- Tesseract 5.5.4 (the engine NewOCR says it uses)
- PDF24
- Chinese
- FastOCR 1.0%OCR.space E3: No scoreOCR.space E2 3.0%Tesseract 71.9%PDF24 3.2%
- Urdu
- FastOCR 9.1%OCR.space E3 19.6%imagetotext.info 9.2%OCR.space E2 30.4%Tesseract 55.3%PDF24 69.0%
- Bengali
- FastOCR 7.4%OCR.space E3 11.2%imagetotext.info 7.9%OCR.space E2 100.0%Tesseract 31.7%PDF24 18.6%
- Arabic
- FastOCR 2.6%OCR.space E3 2.9%imagetotext.info 2.9%OCR.space E2: Not supportedTesseract 20.4%PDF24 35.5%
- Tamil
- FastOCR 2.2%OCR.space E3: No scoreOCR.space E2 99.8%Tesseract 8.5%PDF24 9.2%
- English
- FastOCR 3.3%OCR.space E3: No scoreOCR.space E2 4.5%Tesseract 8.5%PDF24 10.1%
What students use OCR for
Five jobs come up again and again: a photographed page of lecture notes, a textbook chapter, a lecture slide, handwriting, and material in a right-to-left script such as Arabic or Urdu. Each has a different best first move, and the sections below take them in turn.
Lecture notes and textbook pages
Lay the page flat, shoot from straight above in daylight, and upload the photo to Image to Text. A scanned textbook chapter saved as a PDF goes to PDF to Text instead. Either way you get text to search, quote and paste into your notes, plus a searchable PDF of the original.
Read the result once against the page before you cite from it. Names, numbers and chemical or math symbols are where OCR slips first.
Lecture slides and homework pictures
When a lecturer moves on before you finish copying, photograph the slide. For one slide on the spot, Google Lens is the shortest route. For a homework picture or a screenshot of a problem set, upload it to FastOCR, copy the text of each question, and check any equation by eye: we did not measure equations or handwriting.
If the slides are on your laptop screen, the FastOCR Chrome extension copies text from anything on screen.
Handwritten notes
No tool here was measured on handwriting, so there is no accuracy figure for any of them. Tesseract's own FAQ warns that it is designed for printed text, and Google lists handwriting among the things Lens can translate. Neat block capitals in good light have the best chance; expect to correct cursive by hand. The handwriting page lets you try your own notes.
Arabic and Urdu study material
Both scripts run right to left and join their letters, and Urdu is usually printed in slanted Nastaliq. On our Urdu page imagetotext.info and FastOCR were level at 9.2% and 9.1% of characters wrong, while OCR.space Engine 3 got 19.6% and Tesseract 55.3%. On Arabic FastOCR, imagetotext.info and OCR.space Engine 3 were within a point of each other (2.6%, 2.9% and 2.9%) and Tesseract got 20.4%. Lower is better, and gaps under about 3 points are noise.
More detail is in best Urdu OCR tools and best Arabic OCR tools.
OCR tool for Arabic table extraction
FastOCR's Word download rebuilds a table drawn with a line around every cell as a real Word table, with Arabic text running right to left. A table without those lines comes back as lines of text instead. The figure replays that step on a synthetic ruled invoice; it is not a live OCR run. The Arabic table section lists what works and what does not.
In: a ruled Arabic invoice table
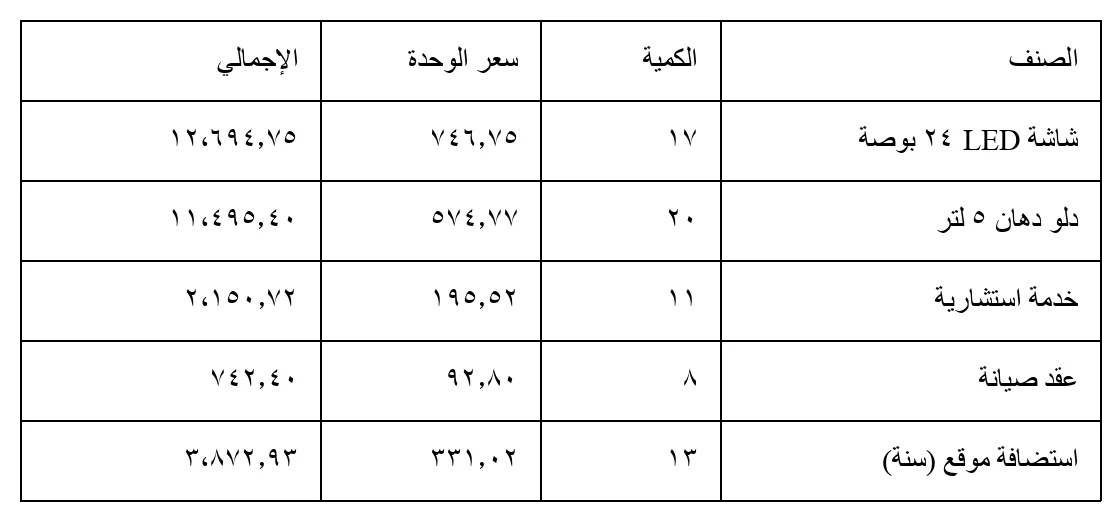
Out: the table in FastOCR's Word file
| الصنف | الكمية | سعر الوحدة | الإجمالي |
| شاشة LED ٢٤ بوصة | ١٧ | ٧٤٦٫٧٥ | ١٢٬٦٩٤٫٧٥ |
| دلو دهان ٥ لتر | ٢٠ | ٥٧٤٫٧٧ | ١١٬٤٩٥٫٤٠ |
| خدمة استشارية | ١١ | ١٩٥٫٥٢ | ٢٬١٥٠٫٧٢ |
| عقد صيانة | ٨ | ٩٢٫٨٠ | ٧٤٢٫٤٠ |
| استضافة موقع (سنة) | ١٣ | ٣٣١٫٠٢ | ٣٬٨٧٢٫٩٣ |
6 rows × 4 columns, each value in its own Word table cell, right to left.
1. FastOCR (our tool)
- Best for
- Scanned textbooks and past papers, Urdu and Arabic study material, and ruled tables going to Word.
- Watch out for
- Images are read one at a time, so a single slide is quicker in Lens. Without an account a small daily image cap applies, and handwriting was not measured.
FastOCR is a website that also works in a phone browser. Each image comes back as raw text and a one-page searchable PDF, with Word and Markdown downloads. A scanned PDF becomes a searchable PDF with a free account. Images need no sign-up and carry no watermark; see pricing.
It reads 100+ languages and detects the language itself. A finished image can be translated for a foreign-language reading or tidied with AI Polish.
For a library without Wi-Fi, free offline Mac and Windows apps in public beta read files on the computer and export text, Word and Markdown; they are not PDF editors.
Scan test, in short: FastOCR got 9.1% of the Urdu page wrong, 2.6% of the Arabic page and 3.3% of the English page, lower is better.
2. Google Lens
- Best for
- One slide, a sign or a paragraph, copied or translated from what the camera sees.
- Watch out for
- It works on a picture, not on a 200-page PDF, and its pages name no scripts it reads.
Lens, per Google, copies text to a phone or computer and translates menus, signs and handwriting in over 100 languages. The translation count is not a list of readable scripts, and none of the pages we read gives one. We did not test its accuracy.
Source: Google Lens, checked 4 November 2026.
3. Google Drive and Docs
- Best for
- A scanned PDF or photo that is already in Drive, when you want a Google Doc.
- Watch out for
- Google says lists, tables, columns and footnotes are not likely to be detected, so a table will not come out as a table.
Google's help page says you can turn a PDF, or a JPEG, PNG or GIF photo, into editable text: right-click the file in Drive and choose Open with Google Docs. The file should be 2 MB or smaller, text at least 10 pixels high, and the image right side up. Drive detects the language and lists Arabic, Urdu and many others.
We did not test its accuracy.
Source: Google Drive Help, checked 4 November 2026.
4. Adobe Acrobat online OCR
- Best for
- A searchable PDF from a scanned PDF when you already have an Adobe account.
- Watch out for
- Adobe says to sign in to download the searchable PDF.
The page is titled Free OCR for PDF. Adobe says the tool applies text recognition to text from images or scanned pages after the file uploads, and that your file is deleted unless you sign in to save it. It does not say what languages the free tool reads.
We did not test it, so there is no Adobe accuracy figure here. Source: Adobe's free OCR page, checked 4 November 2026.
5. Adobe Scan
- Best for
- Scanning paper handouts on the phone into searchable PDFs.
- Watch out for
- Adobe's iOS settings say OCR does not run on scans longer than 25 pages for general users, and its list does not name Arabic, Hindi or Urdu.
Adobe Scan is completely free to download, per Adobe, and its OCR turns scans into editable, searchable PDFs. The iOS settings page names 18 recognition languages, including Chinese, Japanese and Korean. We did not test it.
Source: Adobe Scan and its iOS settings, checked 4 November 2026.
6. Microsoft OneNote
- Best for
- Pulling the text out of a picture you have already pasted into a notebook.
- Watch out for
- Microsoft says some results can take up to 24 to 48 hours, and the page names no languages, limits or price.
Right-click a picture in OneNote and choose Copy Text from Picture, then paste. Microsoft also describes copying text from every page of a printout. The help page says the command may not appear on the menu straight away. We did not test it.
Source: Microsoft's OneNote help, checked 4 November 2026.
7. imagetotext.info
- Best for
- A single Urdu or Arabic page in a free web tool; it matched FastOCR on both in our test.
- Watch out for
- Several files at once need a paid plan, and its language list names 23 languages without Urdu, Persian, Hindi, Bengali or Tamil.
On our Urdu page it got 9.2% of characters wrong and on Arabic 2.9%, level with FastOCR inside the noise. It was not run on the English page. Lower is better.
Its free tier takes one upload at a time.
Source: imagetotext.info, checked 4 November 2026.
8. Tesseract
- Best for
- Students comfortable on a command line who want free, private, offline OCR.
- Watch out for
- There is no window; you run it from a terminal. In our test Urdu and Arabic were well behind the web tools.
With the right language pack it got 8.5% of the English page wrong, 20.4% of the Arabic page and 55.3% of the Urdu page (lower is better). The project is free under the Apache License and trained for more than 100 languages.
Source: Tesseract on GitHub, checked 4 November 2026.
How to extract text from a textbook page or PDF
1. Photograph the page flat and straight, or save the scan as a PDF. 2. Open Image to Text for a photo or PDF to Text for a scan. 3. Upload the file and let the language be detected. 4. Copy the text, or download it. For a ruled table, take the Word download. 5. Read the output against the page, then paste it into your notes.
The file is uploaded to a server to be read, as with any online OCR tool, so read the privacy policy before you send a private exam paper. Tesseract and the free offline Mac and Windows apps keep a file on your own computer.
Photo tips for textbooks and notes
- Daylight beats a desk lamp, which throws shadows across the lines.
- Press a curled page flat; a curved page bends every line.
- Shoot from straight above, since an angle stretches the letters.
- Tap the text to lock focus, and leave the flash off glossy paper.
- Use the full camera resolution for small print.
Languages students ask about
FastOCR reads 100+ languages and has pages for Urdu, Arabic, Hindi and Chinese. We scored Urdu, Arabic and English on this page and the other scripts in best free OCR tools.
How we tested
- Pages: public-domain scanned book pages, one per script. This page shows six: Arabic, Urdu, Bengali, Tamil, Chinese and English. The reference is each page's Wikisource transcription.
- Scoring: wrong characters once spaces, punctuation and Arabic diacritics are removed; lower is better, and a gap under about 3 points is noise.
- Runs: web tools on 31 October 2026, FastOCR output from 25 October 2026; FastOCR read Arabic, Urdu and English at 500 pixels wide and the others at 1,280.
- Not run: Google Lens, Google Drive, OneNote, Adobe and handwriting. Their facts come from each vendor's own pages, read on 4 November 2026.
- OCR.space returned empty results on some pages, which may be rate limiting on its demo key, and Smallpdf refused a second free download.
When another tool is the better choice
- You want one slide or a sign copied right now, on the phone you are holding: Google Lens.
- The scan already lives in Google Drive and a Google Doc is the goal: open it with Google Docs.
- Your notes are in OneNote or you scan paper into the Adobe Scan app.
FAQ
Which is the best free OCR tool for students?
It depends on the job. Google Lens is built for a quick copy from a slide. For a scanned textbook or Urdu or Arabic photos, FastOCR got 9.1% of Urdu characters and 2.6% of Arabic wrong, lower is better; imagetotext.info tied it. We did not test Lens or Drive.
How do I turn lecture notes, textbook pages or a homework picture into editable text?
Photograph the page flat, from straight above, in daylight. Upload it to an image-to-text tool, copy the text and paste it into your notes. Use a PDF tool for a scanned chapter. Check equations and names by eye; we did not measure them.
Does OCR work on handwritten notes?
We did not measure handwriting, so we give no accuracy figure for any tool. OCR is built for printed text, and Tesseract says so in its FAQ. Neat block letters in good light have the best chance; cursive may need many corrections.
Can I extract tables from an Arabic textbook or invoice?
FastOCR finds ruled tables, the kind with a line around every cell, and writes them into its Word download as real Word tables, right to left for Arabic. Tables without lines come out as lines of text. Google says Drive's OCR is not likely to detect tables.
How does Adobe image to text compare with other free tools?
Adobe's free online OCR page is titled Free OCR for PDF and asks you to sign in to download the result. Adobe Scan is free to download, and its iOS settings name 18 languages. We tested neither, so there is no Adobe accuracy figure.
Is OCR for school work free?
Image OCR on FastOCR is free, with no sign-up and no watermark, and a daily cap applies until you sign in. PDFs need a free account. Google Lens and Google Drive are free with a Google account, and Drive reads files of 2 MB or smaller.
Which OCR tool is best for Urdu or Arabic study material?
FastOCR and imagetotext.info were level on both in our test: 9.1% and 9.2% of Urdu characters wrong, 2.6% and 2.9% of Arabic, lower is better. OCR.space Engine 3 matched them on Arabic but got 19.6% on Urdu. Tesseract got 55.3%.
Is it safe to upload my textbook or exam paper?
The file is uploaded to a server to be read, as with any online OCR tool, so read each tool's privacy policy first. FastOCR does not claim HIPAA, GDPR or SOC 2 certification. Tesseract, and the free offline Mac and Windows apps, keep a file on your own computer.
Method
Vendor facts were read on their own pages on 4 November 2026; a fact left out is shown as Not stated, never as No. Google Lens, Google Drive, OneNote, Adobe and handwriting were not run. The scan test counts wrong characters against Wikisource text (lower is better) for one public-domain page per script. Details are in how we tested.
Change log
- 1 April 2026: First published.
- 1 November 2026: Rewritten with a scan accuracy test and sourced Google and Adobe facts.
- 4 November 2026: Moved to the shared comparison template; added OneNote, homework pictures and Arabic table extraction, and re-read every vendor page.